
Search doesn’t rank anymore. It recommends. When someone asks ChatGPT, Claude, Gemini, or Perplexity about solutions in your space, does your brand appear? If AI assistants don’t mention you, you’re invisible to a growing segment of decision-makers who trust AI recommendations over traditional search results.
AI chats influence purchasing decisions, but their recommendations operate like black boxes. Marketing teams lack reliable methods to extract, normalize, and monitor brand mentions across multiple AI platforms. This gap becomes critical when you consider geographic variations, multilingual queries, and the need to track citation quality across ChatGPT, Claude, Gemini, Perplexity, and Grok.
This guide compares the best applications for extracting mentions from AI chats, provides a standard data model for tracking, and shows how to automate reporting and optimization actions. Built for practitioners transitioning from legacy SEO to Generative Engine Optimization (GEO) with enterprise-grade monitoring requirements.
Understanding Mention and Citation Extraction From AI Assistants
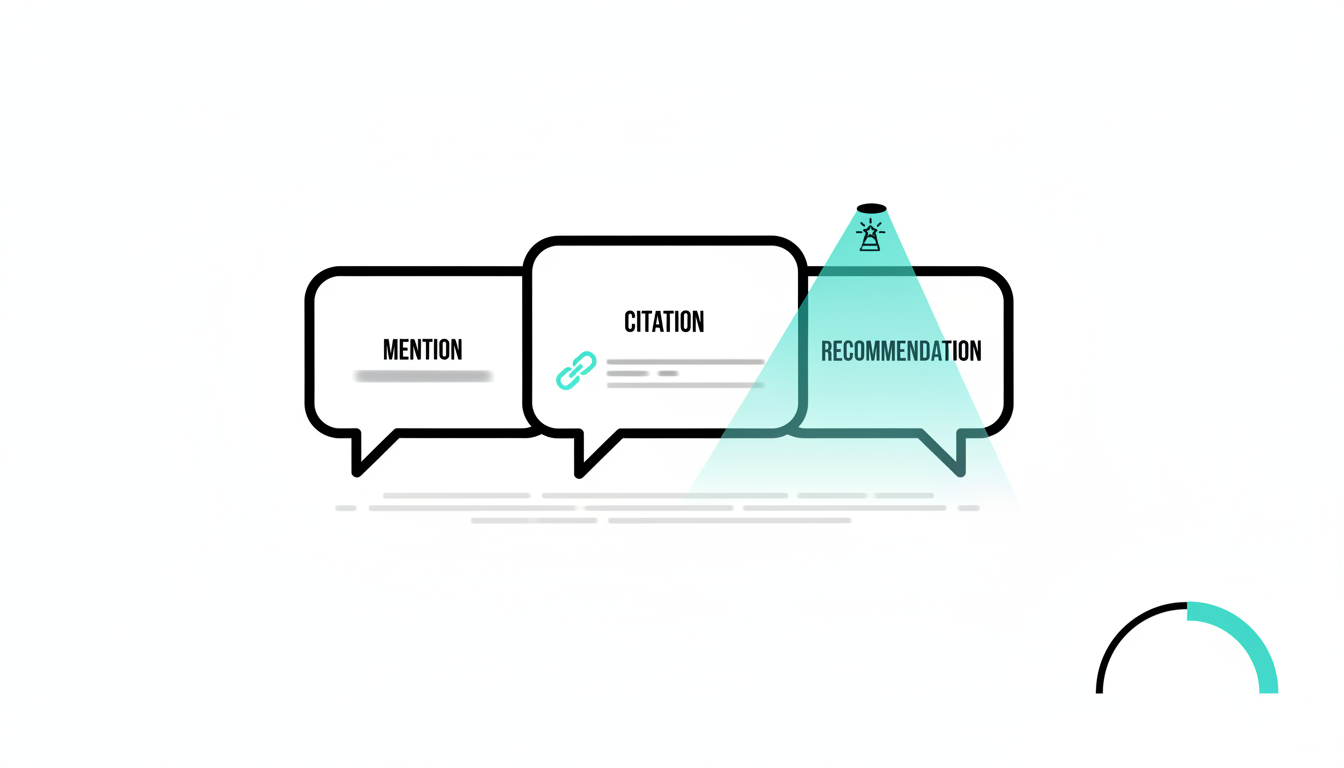
Before evaluating tools, you need clear definitions. A mention occurs when an AI assistant names your brand, product, or company in a response. A citation includes a mention plus a source reference or URL. A recommendation goes further by explicitly suggesting your solution over alternatives.
These distinctions matter because extraction tools handle each type differently. Some capture raw text mentions but miss structured citations. Others parse URLs but fail to associate them with the correct brand entity when multiple products appear in one response.
Data Sources for AI Chat Extraction
Applications pull mention data from several sources, each with trade-offs:
- Chat logs – Direct exports from assistant interfaces (limited by platform access and retention policies)
- Share links – Public conversation URLs that can be scraped (works for ChatGPT shared conversations, Perplexity threads)
- API responses – Structured data from assistant APIs (requires developer access and often costs per query)
- Browser automation – Headless browsers that submit queries and parse responses (scalable but requires infrastructure)
- User-submitted data – Manual uploads or browser extensions (limited scale, introduces sampling bias)
Extraction Challenges That Impact Tool Selection
Several technical obstacles complicate mention extraction. Hallucinations create false positives when assistants invent brand names or misattribute features. Formatting variance across platforms means a tool optimized for ChatGPT’s structured responses may fail on Claude’s conversational format.
Token limits affect context windows. An assistant might mention your brand in a 2,000-word response, but extraction tools working with truncated outputs miss it. Multilingual named entity recognition (NER) becomes critical for global brands – a tool that accurately extracts “Nike” from English queries may fail to catch “耐克” in Chinese responses.
Entity disambiguation presents another hurdle. When an AI mentions “Apple,” does it mean the company, the fruit, or Apple Records? Quality extraction requires confidence scoring and contextual analysis to reduce false matches.
Standard Data Model for Mentions and Citations
Effective monitoring requires a consistent schema across platforms. Here’s a sample JSON structure for a mention object:
{ "mention_id": "m_20250102_chatgpt_abc123", "assistant": "chatgpt", "timestamp": "2025-01-02T14:23:17Z", "locale": "en-US", "city": "San Francisco", "entity": "FAII", "entity_type": "brand", "aliases": ["FAII.AI", "faii"], "confidence": 0.94, "context_snippet": "FAII offers city-level tracking across 195+ countries...", "citation_url": "https://faii.AI/platform", "prompt_id": "p_user_query_xyz", "recommendation_type": "explicit", "position": 2, "competitors_mentioned": ["Brand X", "Brand Y"] }This schema enables cross-platform aggregation, deduplication by prompt and timestamp, and analysis of recommendation context. Fields like city and locale support geographic precision. The position field tracks where you appear relative to competitors.
Key Performance Indicators for AI Chat Visibility
Traditional SEO metrics don’t translate to AI assistants. Instead, track these KPIs:
- Mention rate – Percentage of relevant queries where your brand appears
- Citation quality – Ratio of mentions that include working source URLs
- Share-of-voice – Your mentions divided by total category mentions across assistants
- Recommendation delta – Change in explicit recommendations week-over-week by market
- Position distribution – Where you rank when multiple brands appear (first, second, third mention)
- Geographic coverage – Mention consistency across cities and countries
These metrics connect extraction quality to business outcomes. A tool that captures 95% of mentions with accurate city-level data enables precise optimization. One that misses 30% of citations or aggregates only at country level leaves gaps in your strategy.
Evaluation Criteria for AI Chat Mention Extraction Tools
Selecting the right application requires a framework that goes beyond feature checklists. Use these criteria to assess extraction capabilities and operational fit.
Platform Coverage and Real-Time Monitoring
Does the tool monitor all relevant AI assistants? Comprehensive coverage means tracking ChatGPT, Claude, Gemini, Perplexity, and Grok at minimum. Some tools focus on one or two platforms, creating blind spots in your visibility data.
Real-time monitoring matters when AI recommendations shift rapidly. A tool that queries assistants every 24 hours misses intraday changes. Look for solutions that support scheduled crawls at 1-hour, 4-hour, or custom intervals. Chat Intelligence for cross-platform AI chat mention tracking uses 150 parallel workers to query assistants in real-time across markets.
Extraction Fidelity and Citation Parsing
Fidelity measures how accurately a tool captures mentions without false positives or negatives. Test with known queries where your brand should appear. Run the same queries through competing tools and compare results.
Citation parsing separates basic tools from advanced ones. Can the application extract not just the mention but the source URL, the surrounding context, and the recommendation type? Does it distinguish between a passing mention and an explicit recommendation with a call-to-action?
Multilingual Support and Entity Recognition
Global brands need extraction across languages. A tool with strong English NER but weak performance in Spanish, Mandarin, or Arabic limits your monitoring scope. Test with queries in your target markets.
Entity recognition quality determines whether the tool catches brand aliases and variations. If customers search for “FAII,” “FAII.AI,” “faii platform,” or “Intelligence Squared,” does the extraction system group these as the same entity? Fuzzy matching and entity linking capabilities reduce manual cleanup.
Automation Capabilities: APIs, Webhooks, and Pipelines
Manual extraction doesn’t scale. Evaluate automation depth:
- API access – Can you programmatically submit queries and retrieve structured results?
- Webhook support – Does the tool push new mentions to your data warehouse or BI platform?
- Scheduled jobs – Can you configure recurring extractions without manual intervention?
- Export formats – Does it output CSV, JSON, or direct integrations with BigQuery, Snowflake, or Tableau?
- Event-driven processing – Can you trigger extraction when specific conditions occur (new competitor mention, citation loss)?
Automation reduces manual QA time by 60-80%. Teams move from weekly spreadsheet updates to daily dashboards with real-time alerts when visibility drops or competitors gain mentions.
Governance, Compliance, and Data Retention
Storing AI chat data raises privacy and compliance questions. Does the tool handle personally identifiable information (PII) in user prompts? What retention policies apply to conversation logs?
Look for features like data anonymization, audit trails for who accessed what data, and configurable retention windows. Enterprise teams in regulated industries need tools that support GDPR, CCPA, and industry-specific requirements.
Cost Structure and Scalability
Pricing models vary widely. Some tools charge per query, others per assistant, and some use seat-based licensing. Calculate total cost based on your monitoring volume:
- Number of queries per day across all assistants
- Number of brands or entities to track
- Geographic markets and languages
- Data retention period
- API call volume for automation
Scalability matters when you expand from monitoring 10 queries to 1,000. Does pricing increase linearly or are there volume tiers? Can the infrastructure handle peak loads during product launches or crisis monitoring?
Top Applications for Extracting AI Chat Mentions
These applications represent different approaches to mention and citation extraction. Each serves specific use cases based on platform coverage, automation depth, and operational requirements.
1. FAII Chat Intelligence
FAII Chat Intelligence provides unified monitoring across ChatGPT, Claude, Gemini, Perplexity, and Grok with city-level precision in 195+ countries. The platform combines SERP Intelligence and Chat Intelligence in one interface, enabling teams to track both traditional search visibility and AI assistant recommendations.
Key differentiators include 150 parallel workers for real-time querying, an automated Content & Action Engine that turns mention gaps into optimization tasks, and white-label partnership options for agencies. The Intelligence² approach combines human analysis with AI automation to close the loop from detection to content publishing in 10-15 minutes.
Best for agencies managing multiple enterprise clients who need automated workflows, geographic precision, and the ability to act on insights without switching platforms.
2. BrandWatch AI Listening
BrandWatch extends social listening capabilities to AI assistants with focus on sentiment analysis and conversation context. The platform excels at tracking brand perception across ChatGPT and Perplexity, with strong multilingual NER for European and Asian languages.
Strengths include sentiment scoring, competitor comparison dashboards, and integration with existing BrandWatch social monitoring. Limitations include less comprehensive coverage of Claude and Gemini, and higher latency in real-time monitoring compared to specialized AI visibility tools.
3. Mention Tracker Pro
Mention Tracker Pro focuses on citation extraction with detailed source analysis. The tool parses URLs, validates link quality, and tracks citation changes over time. Particularly strong for B2B SaaS companies monitoring thought leadership and content attribution.
The platform supports scheduled extractions and CSV exports but lacks native API access. Manual configuration required for each new assistant or query set. Best suited for teams with technical resources who can build custom pipelines around the core extraction engine.
4. AI Visibility Monitor
AI Visibility Monitor specializes in competitive intelligence with side-by-side comparisons across assistants. The tool tracks share-of-voice metrics and recommendation positioning, making it easy to benchmark against competitors.
Strong points include visual dashboards, automated weekly reports, and integrations with Slack and email for alerts. Gaps include limited multilingual support (English, Spanish, French only) and country-level rather than city-level geographic tracking.
5. ChatMetrics Enterprise
ChatMetrics targets enterprise compliance and governance use cases. The platform provides detailed audit trails, PII detection, and configurable retention policies. Supports custom entity dictionaries for complex brand hierarchies.
Extraction covers ChatGPT, Claude, and Gemini with API access for automation. Higher price point reflects enterprise features like SSO, role-based access control, and dedicated support. Best for regulated industries or large organizations with strict data governance requirements.
6. Query Insight AI
Query Insight AI takes a research-focused approach with deep analysis of prompt-response pairs. The tool captures full conversation context, not just isolated mentions, enabling teams to understand how questions influence recommendations.
Unique features include prompt engineering suggestions based on mention patterns and A/B testing capabilities for query variations. Limited to ChatGPT and Perplexity currently. Ideal for content strategists optimizing for AI recommendations rather than broad monitoring teams.
Capabilities Matrix: Choosing Based on Your Requirements
Different use cases demand different tool strengths. This analysis maps capabilities to common monitoring scenarios.
Brand Monitoring for Marketing Teams
Marketing teams tracking brand health across AI assistants need comprehensive platform coverage, automated reporting, and easy-to-understand dashboards. Priority features include mention rate tracking, sentiment analysis, and share-of-voice metrics.
FAII Chat Intelligence and AI Visibility Monitor excel here with visual reporting and cross-platform monitoring. BrandWatch AI Listening adds sentiment depth for teams already using BrandWatch for social monitoring. Avoid tools that require technical setup or lack automated alerting.
Competitive Intelligence for Product Teams
Product teams analyzing how AI assistants position competitors need detailed citation analysis, recommendation context, and positioning data. Look for tools that capture where you rank relative to alternatives and what features get highlighted.
Query Insight AI and Mention Tracker Pro provide the deepest competitive context. ChatMetrics Enterprise adds compliance features if you need to store competitor data long-term. Geographic precision matters less for product positioning analysis than extraction fidelity and context capture.
Compliance and Governance for Enterprise
Regulated industries monitoring AI-generated content about their brands need audit trails, PII handling, data retention controls, and role-based access. Extraction accuracy matters less than governance capabilities and security certifications.
ChatMetrics Enterprise leads this category with SOC 2 compliance, configurable retention, and detailed access logs. FAII Chat Intelligence offers enterprise features with white-label options for agencies serving regulated clients. Avoid consumer-grade tools without clear data handling policies.
Agency Client Reporting and White-Label Solutions
Agencies managing multiple clients need multi-tenant architecture, white-label reporting, API access for custom dashboards, and scalable pricing. The ability to brand reports and automate client updates reduces operational overhead.
Watch this video about best applications to extract mentions from ai chats:
FAII Chat Intelligence provides white-label partnerships with 60-70% revenue share, making it viable for agencies to resell as their own service. Mention Tracker Pro offers white-label reporting but lacks multi-tenant user management. BrandWatch requires separate contracts per client, increasing administrative complexity.
Global Brands with Multilingual Requirements
Global brands tracking mentions across markets need multilingual NER, city-level or regional precision, local language query support, and market-specific benchmarking. Extraction must handle character sets, cultural variations in brand names, and regional assistant preferences.
FAII Chat Intelligence monitors 195+ countries with any language combination and city-level precision. BrandWatch AI Listening provides strong European and Asian language support. Other tools typically support English plus 3-5 additional languages, limiting global coverage. For dedicated tracking workflows, see how to track brand mentions in AI.
Implementation: Building Your Extraction Pipeline
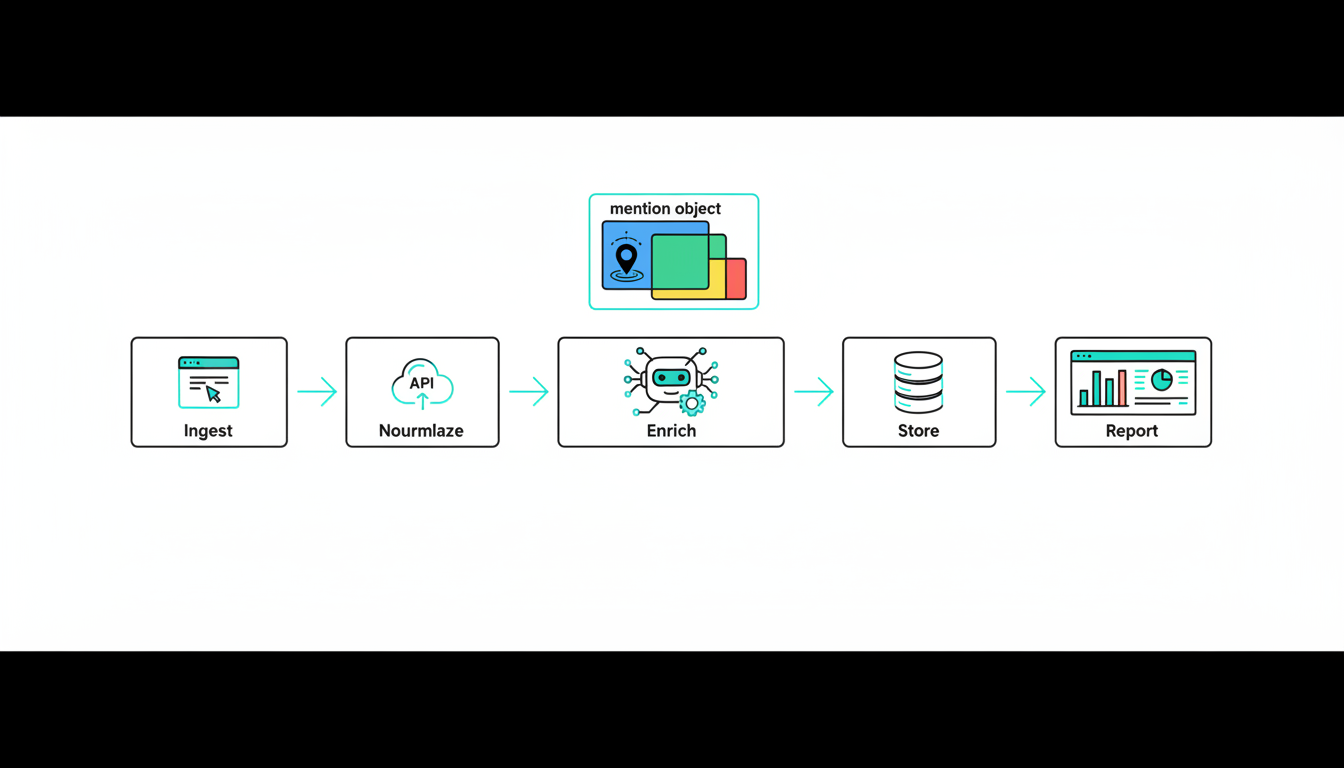
Selecting a tool is step one. Operationalizing extraction requires a structured pipeline that transforms raw mentions into actionable insights.
Quick-Start Pipeline Architecture
A functional extraction pipeline follows five stages:
- Ingest – Collect raw data from assistants via APIs, scraping, or manual uploads
- Normalize – Standardize formats across platforms using your data model schema
- Enrich – Apply NER, entity linking, sentiment scoring, and confidence calculations
- Store – Load structured data into your warehouse with deduplication and indexing
- Report – Generate dashboards, alerts, and exports for stakeholders
This architecture separates data collection from analysis, enabling you to swap extraction tools without rebuilding downstream processes. Store raw responses alongside processed mentions for audit trails and reprocessing when algorithms improve.
Automation Recipes for Common Workflows
These automation patterns reduce manual work and improve data freshness:
- Scheduled crawls – Run queries every 4 hours, store results, compare to baseline, alert on significant changes
- Event-driven extraction – Trigger extraction when competitors launch products, you publish new content, or industry news breaks
- Webhook pipelines – Push new mentions directly to Slack, BigQuery, or your CRM as they occur
- Batch processing – Queue queries during off-peak hours to reduce API costs while maintaining daily coverage
- Incremental updates – Extract only new or changed mentions since last run to minimize processing overhead
Start with scheduled crawls for baseline monitoring. Add event-driven extraction as your monitoring matures and you identify high-value trigger conditions. See the full platform capabilities for examples of end-to-end automated workflows.
Governance Checklist for AI Chat Data
Before storing mention data, address these governance requirements:
- PII detection – Scan prompts and responses for personal information, redact or anonymize before storage
- Retention policies – Define how long to store raw responses (30 days), processed mentions (1 year), and aggregated reports (indefinitely)
- Access controls – Limit who can view raw conversation data vs. aggregated metrics
- Audit trails – Log all access to mention data with timestamps and user IDs
- Model versioning – Track which NER and extraction algorithms processed each mention for reproducibility
- Data lineage – Document source assistant, query timestamp, and processing pipeline for each mention
Governance protects your organization and builds trust with stakeholders who rely on mention data for decisions. Document policies before extraction begins, not after compliance questions arise.
Dashboard Blueprint for Stakeholder Reporting
Effective dashboards answer specific questions without overwhelming users. Structure reports around these views:
Executive summary – Weekly mention rate, citation quality percentage, share-of-voice vs. top 3 competitors, trend arrows (up/down/flat)
Platform breakdown – Mentions by assistant (ChatGPT, Claude, Gemini, Perplexity, Grok) with change from prior period
Geographic heatmap – City-level or regional mention density with filters for language and market
Competitive positioning – Where your brand ranks when mentioned alongside competitors, average position, position distribution
Citation analysis – Ratio of mentions with working URLs, top cited pages, citation quality score over time
Recommendation context – Sample responses showing how assistants describe your brand, common feature callouts, sentiment tone
Refresh dashboards daily for operational teams, weekly for executives. Use Get Your AI Visibility Score as a baseline metric to track improvement over time.
Template Pack for Faster Implementation
These templates accelerate pipeline setup and standardize processes:
- Evaluator checklist – Criteria matrix for scoring extraction tools during vendor selection
- Data model schema – JSON and CSV templates with required fields for mentions and citations
- SQL deduplication queries – Remove duplicate mentions based on prompt, timestamp, and entity
- Dashboard wireframes – Mockups for executive, operational, and competitive intelligence views
- Governance policy template – Customizable document covering retention, access, and compliance
- Automation runbook – Step-by-step instructions for setting up scheduled crawls and webhooks
Templates reduce implementation time from weeks to days. Customize based on your organization’s requirements but maintain core structure for consistency across teams.
Connecting Extraction to Generative Engine Optimization Outcomes
Mention data becomes valuable when tied to business results. GEO strategies depend on accurate extraction to measure what works.
From Mentions to Optimization Actions
Extraction reveals gaps that inform content strategy. If your brand appears in 40% of relevant queries on ChatGPT but only 15% on Claude, investigate why. Do you lack citations in sources Claude prefers? Does your content use terminology Claude’s training data emphasizes?
Map mention patterns to content creation priorities. Low citation quality suggests your existing content lacks the structure or authority AI assistants value. Missing mentions in specific markets indicate localization gaps or regional content deficits.
The automated Content & Action Engine demonstrates this connection by detecting mention gaps and generating optimized content to close them. Manual processes achieve similar results but require more time between detection and action.
Revenue Signals and Attribution
Connect mention tracking to revenue by analyzing which assistants drive conversions. If prospects mention discovering your brand through Perplexity, prioritize optimization for that platform. Track deal velocity and close rates segmented by discovery source (ChatGPT, Claude, traditional search).
Attribution gets complex when buyers use multiple assistants during research. Implement UTM parameters or unique landing pages for each assistant to isolate traffic sources. Correlate mention rate increases with lead volume changes to quantify GEO impact.
Multilingual and Multi-Market Considerations
City-level extraction enables precise geographic optimization. If your brand gets mentioned in New York but not Los Angeles for the same query, investigate local content gaps or citation sources.
Multilingual monitoring reveals translation and localization opportunities. A brand mentioned frequently in English queries but rarely in Spanish suggests content gaps or entity recognition issues with translated brand names. Test extraction with your brand name in target languages to verify accuracy before drawing conclusions.
Frequently Asked Questions
How accurate are AI chat mention extraction tools?
Accuracy varies by platform coverage, NER quality, and entity disambiguation capabilities. Top-tier tools achieve 90-95% precision on English queries with well-known brands. Accuracy drops for niche entities, multilingual queries, or assistants with less structured outputs. Test with known queries where you control ground truth before trusting extraction data for decisions.
Can I extract mentions from proprietary AI assistants built on ChatGPT or Claude APIs?
Yes, if you have access to conversation logs or API responses. Custom assistants built on foundation models produce extractable outputs using the same techniques as public assistants. You may need custom entity dictionaries if your proprietary assistant uses domain-specific terminology. Governance policies apply – ensure you have rights to store and analyze user conversations.
What’s the difference between real-time and scheduled extraction?
Real-time extraction queries assistants continuously or on-demand, capturing mentions within minutes of occurrence. Scheduled extraction runs at fixed intervals (hourly, daily). Real-time costs more due to API usage and infrastructure but provides immediate alerts. Scheduled extraction suffices for most monitoring use cases unless you need crisis response or track rapidly changing topics.
How do I handle false positives when my brand name matches common words?
Implement confidence scoring and contextual analysis. Tools with strong NER use surrounding text to disambiguate entities. If your brand is “Apple,” the system should distinguish between technology mentions and fruit references based on context. Configure entity dictionaries with aliases and exclusion patterns. Review false positives manually during initial setup to tune filters.
Should I extract from AI assistants I don’t optimize for?
Yes. Monitoring all major assistants reveals where you have organic visibility without optimization effort. These platforms may become priorities as usage grows. Comprehensive monitoring also provides competitive intelligence – if competitors gain mentions on platforms you ignore, you miss strategic threats. Start with broad coverage, then focus optimization based on mention patterns and business priorities.
How often should I update my extraction queries and entity dictionaries?
Review monthly for the first quarter, then quarterly once stable. Update when you launch products, rebrand, or enter new markets. Monitor extraction quality metrics – if false positive rates increase or you see mentions you’re not capturing, update entity dictionaries and test queries. AI assistant behaviors change as models update, requiring periodic recalibration.
Making AI Chats Measurable and Actionable
You now have a framework for evaluating extraction tools, a standard data model for mentions and citations, and implementation patterns for automation and reporting. The applications covered represent different strengths – comprehensive cross-platform monitoring, deep competitive analysis, enterprise governance, or agency white-label capabilities.
Start with these priorities:
- Use standardized evaluation criteria to shortlist tools that match your platform coverage and automation requirements
- Adopt a portable data model so you can aggregate mentions across tools and platforms
- Automate enrichment and reporting to move from data collection to optimization actions
- Track multilingual and city-level visibility for geographic precision
- Connect extraction quality to GEO outcomes and revenue signals
AI assistants will continue influencing purchase decisions. Brands that measure and optimize their visibility in AI recommendations gain competitive advantages. Those that remain invisible lose ground to competitors who treat AI chats as seriously as traditional search.
The difference between monitoring and optimization is action. Extraction tools provide data. What you do with that data determines whether you influence AI recommendations or watch competitors capture mindshare in the channels that matter most to your next customers.