
Marketing leaders face a massive shift in search behavior. Buyers now ask chatbots for software suggestions before visiting your website. Traditional metrics miss these AI-generated recommendations entirely. You might ask How can I measure brand visibility in ChatGPT and AI search results? You can measure this by running standardized prompts across major models. You capture brand mentions, recommendation frequency, and citations. Then you calculate your AI share of voice.
Chat models vary by mode, region, and recency. They often omit or mangle citations. This creates a tracking challenge for B2B SaaS marketing teams. You need reproducible metrics to tie brand mentions to your pipeline. Executives demand hard numbers on mention rates and recommendation frequency.
This guide outlines a reproducible measurement workflow. You will learn sampling design, prompt controls, and citation parsing. This process aligns with current web-enabled model behaviors. You will discover how to track brand mention monitoring accurately.
- Run standardized prompts across major models consistently
- Capture exact brand mentions and contextual citations
- Calculate AI share of voice over time accurately
- Roll up detailed diagnostics to an executive-friendly index
Why AI Brand Visibility Matters
AI assistants increasingly intermediate discovery and recommendations. Buyers trust these systems to curate their options. This shifts traffic away from traditional search engines. You must track this shift to protect your market share. If your brand is missing from these answers, you lose pipeline.
Executives demand measurable, comparable indices. They want hard numbers on mention rates and recommendation frequency. They need to see a clear return on investment. You must quantify your brand recommendation frequency in AI systems. A feeling of visibility is not enough. You need hard data.
Measurement informs your content remediation strategy. It highlights gaps in your current messaging. Data guides your partner and PR prioritization efforts. You can focus resources on the channels that generate actual pipeline.
- AI Overviews tracking reveals your true search presence
- Measurement highlights specific content gaps and opportunities
- Data guides your partner and PR prioritization effectively
- Accurate tracking proves the value of your marketing efforts
How AI Systems Generate Answers and Cite Sources
Models use retrieval and grounding to build responses. Web-enabled modes fetch live pages to answer queries. This allows them to provide up-to-date information. Retrieval augmented generation anchors outputs to specific sources. This process dictates if your brand appears in the answer. Understanding this mechanism is crucial for accurate measurement.
Some models show clear links to your website. Others paraphrase information without explicit attributions. This makes tracking chat assistant citations difficult. You must understand these differences to measure your visibility accurately. A mention without a link still holds brand value. A direct citation drives actual referral traffic.
Model modes dictate citation behavior heavily. A no-web mode relies on training data alone. Web modes pull fresh search results to build answers. GPT-5 class performance improves significantly with web access. You must test both modes to get a complete picture.
- Web-enabled models fetch current pages for fresh data
- No-web modes rely entirely on older training data
- Citation formats vary wildly across different platforms
- Search-grounded models provide more accurate source links
You must verify outputs to control for errors. Read about hallucination risk and verification methods at AI Hallucination Mitigation.
Measurement Methodology
A structured approach prevents skewed data. You need a consistent process to track AI visibility metrics for brands. This step-by-step methodology provides a reliable framework. Random testing yields useless data. You must build a rigorous testing environment.
Define Your Query Set
Build a list of product, category, and competitor prompts. Include queries like “best CRM for startups” or “SOC 2 compliance software”. Track prompt versioning to maintain consistency across tests. Consistent prompts yield comparable data over time. Document every prompt variation carefully.
Cross-Model Sampling
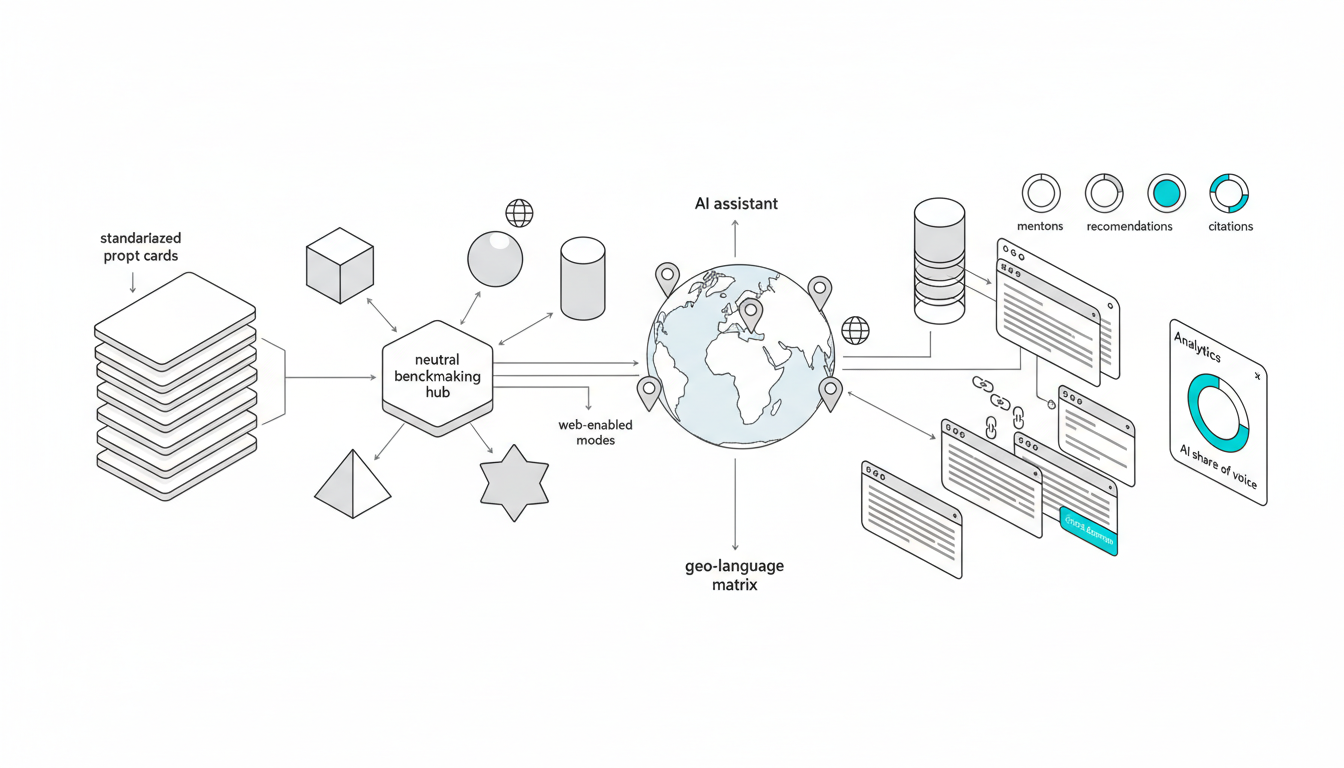
Run identical prompts across ChatGPT, Claude, Gemini, Grok, and Perplexity. Always include web-enabled modes where available. Use a neutral benchmarking utility like Suprmind. This runs the same prompt across multiple models to compare answers. Multi-model benchmarking reveals platform-specific biases.
Geo and Language Matrix
Test priority cities and markets systematically. Create a geo-language matrix for your target regions. Schedule a weekly cadence for volatile software categories. Consistent scheduling builds a reliable data timeline. Localized testing reveals regional brand strength.
Capture Outputs and Parse Entities
Store raw text, displayed citations, and linked sources. Record the model, mode, time, and locale for every test. Detect exact and fuzzy brand mentions in the text. Look for recommendatory language and map URLs to your domain. This parsing step requires meticulous attention to detail.
- Compute your baseline mention rate accurately
- Calculate your exact brand recommendation frequency
- Measure your precise citation frequency across models
- Determine your true AI share of voice
Trend and QA
Compare week-over-week deltas to spot anomalies. Re-run discrepant samples to check stability and reduce errors. Citing research on hallucinations impacting measurement confidence helps set expectations. Review the statistics at see more.
Metrics Definitions and Formulas
Clear definitions keep your reporting accurate. Use these standard formulas to calculate your visibility score. These metrics provide a clear picture of your performance. Do not mix these metrics in your reports.
Core Measurement Metrics
AI Brand Mentions count explicit or clear implicit brand references per run. This forms your baseline visibility metric. Count every instance where a model names your product. Do not count generic category terms.
Recommendation Frequency tracks the percentage of runs that explicitly recommend your brand. Weight this higher than unlinked mentions in your reports. A recommendation carries more weight than a passing mention. It signals high trust from the model.
Citation Frequency measures the percentage of runs with at least one URL pointing to your domain. This tracks direct traffic potential from AI answers. Citations prove the model trusts your specific content.
- Mention Rate = total brand mentions / total runs
- Recommendation Frequency = recommendations including brand / total runs
- Citation Frequency = runs citing your domain / total runs
- AI SOV = your mentions / sum of all tracked brand mentions
Coverage and Trends
Model Coverage identifies the models and locales where your brand appears at least once. Visibility Trend shows the directional change across periods. Always report these trends with confidence intervals. Executives need to understand the margin of error.
Track web-enabled and no-web results separately. Web access improves performance in many studies. RAG evaluation shows reduced hallucinations when models cite sources. Separate these metrics to show clear performance differences.
Verification and Reliability
Chat models generate inconsistent answers frequently. You must build verification steps into your measurement pipeline. This prevents reporting inaccurate data to your executives. Trust in your data is paramount.
Watch this video about How can I measure brand visibility in ChatGPT and AI search results?:
Sampling and Cross-Checking
Re-run a 10 to 20 percent sample to estimate variability. Flag large deltas for manual review immediately. This catches temporary model glitches or updates. Consistent re-sampling builds confidence in your reporting.
Cross-check that citations resolve to live pages. Detect redirects and canonical domains to guarantee accurate tracking. Broken links in AI answers hurt your brand credibility. You must fix broken citations quickly.
- Maintain a detailed prompt changelog for audits
- Pin specific model versions where possible
- Use RAG-grounded prompts for validation runs
- Document all model modes used during testing
RAG drastically reduces hallucinations during testing. Keep your mitigation strategies updated based on current model behaviors. Document your prompt versions and model modes carefully. Consistency is the key to reliable data.
Action Workflow From Measurement to Execution
Measurement must lead directly to action. You need a workflow that bridges data to content publishing. This turns raw metrics into pipeline growth. Data without action is useless overhead.
The Five-Step Loop
First, monitor outputs across models and locales. Log your metrics to detect baseline performance accurately. Second, diagnose missing citations and weak categories. Identify low-coverage locales that need immediate attention. Find the exact queries where competitors beat you.
Third, produce content that answers the exact prompts. Use credible sources and apply generative engine optimization. Fourth, ship to your CMS and add structured data. Distribute the content to authoritative channels. Make it easy for models to crawl your new pages.
Fifth, compare deltas and adjust your prompts. Measure again to track your progress over time. Transition to GEO Tools for setting up automated monitoring.
- Get Your AI Visibility Score to roll up composite indices
- Track AI Overviews to capture geographic variance
- Monitor ChatGPT mentions during cross-model chat sampling
- Use AI Website Analytics to see what content models consume
- Use automated content execution to close visibility gaps
- Learn more about this topic by exploring the platform overview
Practical Example
Let us look at a real-world B2B SaaS scenario. A marketing team wants to track chatbot recommendation monitoring. They need auditable metrics for their executive board. They need to prove their value.
They select 50 category and competitor prompts. They run these in US English, UK English, and German. This covers their primary target markets comprehensively. They document every prompt version carefully.
- Run prompts across ChatGPT, Claude, and Gemini
- Include Grok and Perplexity with web-on modes
- Execute tests three times per week consistently
- Log all raw outputs for future auditing
The team computes their SOV and citation frequency. They prioritize topics with high mention rates but low citations. They use a neutral benchmarking tool to run multi-model tests. This surfaces disagreements between different AI assistants. They use this data to build a targeted content calendar.
Key Takeaways
Measuring your presence in AI search requires discipline. You must build a structured, repeatable process. A consistent approach yields reliable executive reports. It transforms raw data into a clear action plan.
A complete AI visibility platform shows how AI systems perceive your brand. It automatically closes identified gaps with content creation, publishing, amplification, and measurement in one system. You must adapt to changing model behaviors quickly. Build a robust testing framework today. Do not wait for traditional SEO tools to catch up. Take control of your AI visibility now.
- Standardize prompts, modes, and locales for comparable results
- Track mentions, recommendations, and citations thoroughly
- Report AI SOV with confidence intervals by model
- Create and publish content to address detected gaps
- Re-run verification samples to maintain data integrity
Frequently Asked Questions
How often should I measure AI visibility?
Test weekly for volatile categories. Use a biweekly or monthly cadence for stable niches. Always re-run a verification sample to catch anomalies. Consistent scheduling builds a reliable data timeline over months and years.
Do all chat models show citations?
No. Some provide links in web-enabled modes. Others may paraphrase sources without linking. Track both mentions and citations to get a complete picture of your brand presence. Different models have different display rules.
What if my brand is mentioned without a link?
Count it toward your mentions and SOV. Prioritize content that earns citations and recommendations to strengthen your authority. Unlinked mentions still build brand awareness with the end user. They hold significant marketing value.
How do I handle different geographies and languages?
Create a geo-language matrix and schedule runs per market. Report your coverage and trends separately by locale. AI answers vary wildly based on the user location and language settings.
Can I reduce errors in measurement?
Yes. Use web-enabled modes and RAG-grounded verification runs. Document your prompt versions and model modes carefully. Regular re-sampling helps catch temporary model glitches and reduces false positives in your reporting.