
Your executives want to know what ChatGPT says about your brand. Your competitors are getting recommended while you’re invisible. Without a reliable monitoring system, you’re operating blind in the channel where purchase decisions start.
Teams scramble to manually check ChatGPT responses. There’s no audit trail, no alerts when your brand appears or disappears, and no way to track market-by-market changes. Meanwhile, your share of voice in AI recommendations drops.
You need a real-time monitoring workflow that logs citations, alerts your team instantly, and turns detections into action. This guide shows you how to build it.
How Chat Engines Form Brand Recommendations
ChatGPT builds brand recommendations from multiple signals. Understanding these mechanics explains why your brand appears in some responses but not others.
Entity Understanding and Knowledge Sources
Chat engines synthesize information from documentation, reviews, knowledge graphs, and indexed content. Your brand’s entity strength determines whether ChatGPT recognizes you as a relevant solution.
- Structured data and schema markup help ChatGPT understand your brand attributes
- Review platforms and third-party citations reinforce your category positioning
- Knowledge graph connections link your brand to relevant problems and solutions
- E-E-A-T signals from authoritative content establish credibility
If your brand lacks strong entity signals, ChatGPT treats you as unknown even when you’re the best solution. Monitoring AI brand mentions helps you identify these visibility gaps before they cost you deals.
Session Variability and Prompt Sensitivity
ChatGPT responses vary between sessions. The same prompt produces different recommendations based on conversation context, model temperature settings, and retrieval patterns.
Test the same commercial-intent prompt across ten sessions. You’ll see different brands mentioned, different ordering, and different levels of detail. This session variability means single-check monitoring produces unreliable data.
Localization Effects: City-Level and Language Differences
ChatGPT tailors recommendations based on user location and language. A query for “best CRM software” in San Francisco returns different results than the same query in London or Tokyo.
- City-level testing reveals geographic blind spots in your visibility
- Language variations affect translation quality and brand name consistency
- Regional competitors dominate local recommendations
- Market-specific content gaps become obvious through localized monitoring
Without city-level tracking, you miss revenue opportunities in markets where you’re invisible. Your global visibility strategy needs local precision.
Model Updates and Content Freshness
OpenAI updates ChatGPT regularly. Each update changes how the model processes queries, weights sources, and forms recommendations. Your brand’s inclusion rate shifts after every major release.
Content freshness matters. ChatGPT favors recent, well-maintained information over outdated pages. If your competitors publish more frequently, they gain recommendation priority.
Monitoring Architecture for Real-Time Detection
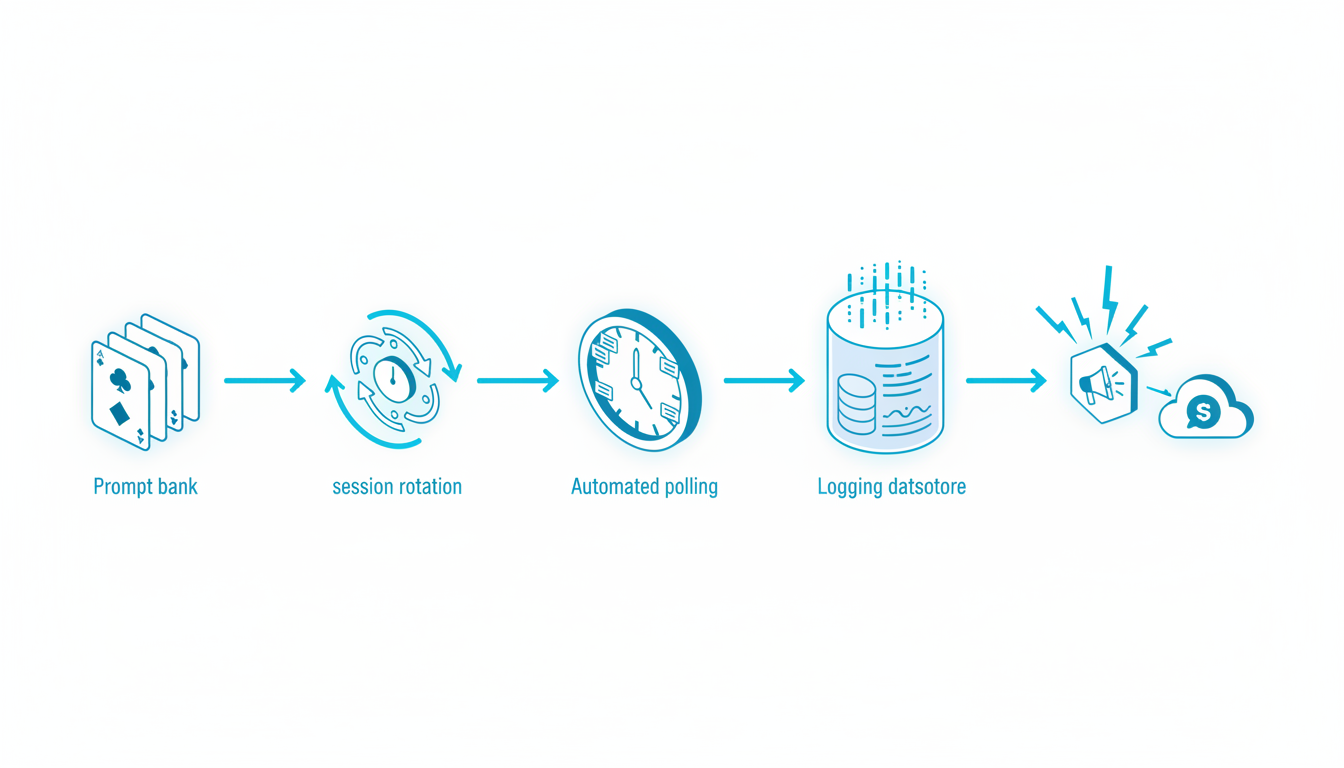
Reliable live monitoring requires five core components working together. Skip any component and your system produces incomplete or misleading data.
Prompt Bank for Consistent Queries
Build a library of prompts that trigger recommendation contexts where your brand should appear. Your prompt bank needs commercial-intent queries, definitional questions, and troubleshooting scenarios.
- Commercial queries: “best [category] for [use case]” and “top [solution type] for [industry]”
- Definitional prompts: “what is [category]” and “how does [solution type] work”
- Troubleshooting scenarios: “how to solve [problem]” and “[problem] solutions”
- Negative tests: queries where your brand should not appear
Version your prompts. Track which variations produce the most reliable detection signals. Remove prompts that generate inconsistent or irrelevant responses.
Session Control and Rotation Strategy
Single-session checks miss the variability problem. Your monitoring system needs to query ChatGPT multiple times per prompt, rotating sessions to capture response distribution.
Run each prompt across three to five sessions within a short time window. Log all responses. Calculate mention rate as the percentage of sessions where your brand appears.
- Session rotation reduces bias from conversation history
- Multiple samples reveal consistency or volatility in recommendations
- Response distribution shows your competitive position
- Outlier detection identifies hallucinations or errors
Automated Scheduler for Polling Intervals
Manual checking doesn’t scale. Your system needs automated scheduling to query ChatGPT at defined intervals without human intervention.
Set polling frequency based on business priorities. High-value keywords need hourly or daily checks. Lower-priority terms can run weekly. Your scheduler must handle rate limits and retry logic.
Logging Datastore Schema
Every detection needs structured logging. Your datastore captures query details, response content, citations, timestamps, and metadata for analysis.
Required fields for each log entry:
- query_id: unique identifier for tracking
- prompt: exact text sent to ChatGPT
- model: ChatGPT version (GPT-4, GPT-3.5, etc.)
- locale_city: geographic location for the query
- language: query and response language
- timestamp: UTC datetime of query execution
- response_excerpt: relevant portion of ChatGPT’s answer
- citation_urls: any sources ChatGPT referenced
- mentioned_brand: boolean flag for your brand presence
- confidence: detection confidence score
- reviewer_id: who verified the detection
This schema enables time-series analysis, localization comparison, and audit trails. Export logs to CSV or JSON for reporting and visualization.
Alerting System Configuration
Detections without alerts create data graveyards. Your monitoring system needs real-time notifications when significant events occur.
Configure alerts for three event types:
- Positive mention: your brand appears in a recommendation
- Negative mention: your brand is criticized or misrepresented
- Omission: your brand is absent from a query where you should rank
Route alerts to the right channels. Email works for daily summaries. Slack or Teams enable immediate response to critical changes. Set thresholds to avoid alert fatigue.
Rate Limits and Ethical Usage
Respect OpenAI’s terms of service. Excessive querying risks account suspension. Your monitoring system needs rate limiting and respectful usage patterns.
Implement delays between queries. Spread checks across time windows. Use API access where available instead of web scraping. Document your monitoring practices for compliance reviews.
Building Your Prompt Bank
Your prompt bank determines what you can detect. Poor prompts produce unreliable signals. Strategic prompts reveal actionable visibility gaps.
Commercial-Intent Prompts
These prompts trigger buying-mode responses where ChatGPT recommends specific brands. Focus on queries your prospects actually use.
- “best [category] for [specific use case]”
- “top [solution type] for [industry/role]”
- “[category] comparison for [buyer type]”
- “recommended [tools/services] for [job-to-be-done]”
Include variations with different qualifiers: budget-friendly, enterprise-grade, beginner-friendly, advanced features. Each variation tests different positioning angles.
Definitional and Educational Prompts
Brand mentions in educational content build awareness. These prompts test whether ChatGPT associates your brand with category definitions.
Examples include “what is [category],” “how does [solution type] work,” and “explain [concept] with examples.” Your brand should appear in explanations and example lists.
Troubleshooting and Solution Prompts
Prospects search for solutions to specific problems. These prompts test whether ChatGPT recommends your brand as a fix.
- “how to solve [specific problem]”
- “fix [error/issue] in [context]”
- “alternatives to [competitor] for [use case]”
- “migrate from [old solution] to [category]”
Negative Testing Prompts
Not every query should mention your brand. Negative tests verify your monitoring system doesn’t produce false positives.
Create prompts for adjacent categories, competitor-specific queries, and irrelevant use cases. If your brand appears in these responses, you’ve detected either hallucination or category confusion.
Prompt Performance Tracking
Track which prompts consistently trigger brand mentions. High-performing prompts become your baseline for measuring visibility changes. Low-performing prompts reveal content gaps.
Maintain a performance dashboard showing mention rate per prompt over time. Retire prompts that produce unstable or irrelevant results. Add new prompts based on keyword research and customer queries.
Localization and Language Coverage

ChatGPT responses vary dramatically by location and language. Your monitoring strategy needs geographic precision to capture real visibility.
City-Level Testing Strategy
Country-level tracking misses regional variations. City-level testing reveals where your brand dominates and where you’re invisible.
Prioritize cities by revenue potential and market maturity. Test major metros in your core markets first. Expand to secondary cities as your monitoring capacity grows.
- North America: New York, San Francisco, Toronto, Austin, Chicago
- Europe: London, Berlin, Paris, Amsterdam, Stockholm
- Asia-Pacific: Singapore, Tokyo, Sydney, Bangalore, Hong Kong
- Emerging markets: São Paulo, Dubai, Tel Aviv, Mexico City
Run identical prompts from each city. Compare mention rates and recommendation positioning. Geographic blind spots indicate localization gaps in your content or entity signals.
Language Variations and Translation Quality
Test prompts in languages your customers speak. ChatGPT’s recommendations shift when queries use non-English languages.
Your brand name might be transliterated differently across languages. Product terminology varies by region. Category definitions don’t translate directly. These variations affect whether ChatGPT recognizes and recommends your brand.
Market Prioritization Framework
You can’t monitor everywhere at once. Prioritize markets based on three factors:
- Revenue contribution: current and projected
- Competitive intensity: how aggressively competitors target the market
- Risk exposure: regulatory requirements and reputation sensitivity
High-revenue markets with strong competition need daily monitoring. Emerging markets with low current revenue can run weekly checks. Adjust frequency as markets mature.
Visualization: Mention Rate by Location
Create heatmaps showing your mention rate across cities and languages. Color-code by performance: green for strong visibility, yellow for moderate, red for invisible.
These visualizations make geographic gaps obvious to executives. They guide localization investment decisions and content prioritization. Update heatmaps monthly to track improvement.
Verification and Quality Assurance
Automated monitoring produces false positives. Your system needs verification layers to ensure data accuracy before alerting teams or making decisions.
Cross-Session Confirmation
A brand mention in one session might be a hallucination or random variation. Require mentions in multiple sessions before logging as confirmed detection.
Set a confirmation threshold: brand must appear in at least 40-60% of sessions to count as reliable mention. Lower thresholds increase false positives. Higher thresholds miss real but inconsistent mentions.
Citations Parsing and Source Validation
When ChatGPT cites sources, verify the URLs actually mention your brand. Parse citation links and check if they’re authoritative, relevant, and accurate.
- Extract all URLs from ChatGPT responses
- Verify each URL resolves and contains brand references
- Check source authority and publication date
- Flag citations from low-quality or irrelevant sources
Citation quality matters as much as mention presence. A recommendation backed by authoritative sources carries more weight than unsupported claims.
Manual Review Checklist for Sensitive Claims
Some detections need human verification before action. Build a review queue for sensitive scenarios:
- Negative mentions or criticism
- Competitor comparisons with specific claims
- Pricing or feature assertions
- Regulatory or compliance-related statements
Assign reviewers to verify context, accuracy, and appropriate response. Document review decisions for audit trails.
Governance: Audit Logs and Access Controls
Your monitoring system handles sensitive competitive intelligence. Implement access controls and audit logging to maintain data security.
Track who queries the system, what data they access, and what actions they take. Restrict access to monitoring dashboards and raw logs. Set retention policies for stored responses.
Alerting, Thresholds, and On-Call Response
Monitoring without action wastes resources. Your alerting system needs clear rules, appropriate thresholds, and defined response workflows.
Event Types and Alert Rules
Configure alerts for three primary event types, each with different urgency and routing.
Positive mention alerts fire when your brand appears in target prompts. These are low-urgency wins worth tracking but don’t require immediate action.
Negative mention alerts trigger when ChatGPT criticizes your brand or recommends competitors instead. These need rapid response to understand root causes.
Omission alerts activate when your brand disappears from prompts where you previously ranked. These signal visibility loss and require investigation.
Threshold Configuration
Set thresholds based on mention rate and share-of-voice changes. Avoid alert fatigue from minor fluctuations.
- Mention rate drop of 20%+ in 24 hours: high-priority alert
- New competitor appears in 3+ consecutive sessions: medium-priority alert
- Negative sentiment detected: immediate alert regardless of frequency
- Share-of-voice shift of 15%+ week-over-week: weekly summary alert
Tune thresholds based on your business context. High-velocity markets need tighter thresholds. Stable categories can tolerate wider bands.
Routing to Channel Owners
Different alerts need different owners. Route notifications to teams who can take action.
Watch this video about monitor brand references in chatgpt live:
- SEO team: content gaps and entity optimization needs
- Content team: messaging inconsistencies and missing topics
- PR team: negative mentions and reputation issues
- Product team: feature comparisons and positioning challenges
- Support team: troubleshooting queries and solution recommendations
Use Slack channels, email lists, or ticketing systems to route alerts. Include context: the prompt, response excerpt, session count, and suggested next steps.
Post-Incident Review Template
When significant visibility changes occur, conduct structured reviews to understand causes and prevent recurrence.
Document what changed, when it changed, likely causes, and actions taken. Track time-to-detection and time-to-resolution. Identify process improvements for future incidents.
From Detection to Action: Closing the Loop
Monitoring reveals gaps. Action closes them. Your workflow needs to connect detections directly to content updates, entity optimization, and visibility improvements.
Entity Optimization for Stronger Recognition
When ChatGPT doesn’t recognize your brand, strengthen your entity signals. This means structured data, knowledge graph presence, and authoritative content assets.
- Add schema markup to key pages: Organization, Product, Review, FAQ
- Create and optimize your Knowledge Graph entity
- Build E-E-A-T content that establishes category authority
- Secure citations from authoritative third-party sources
Entity optimization takes weeks to propagate. Track mention rate changes after entity updates to measure impact.
Source Reinforcement Strategy
Identify pages ChatGPT already uses as sources. Strengthen these pages to reinforce accurate brand information.
Parse citation URLs from your monitoring logs. Find common sources ChatGPT references for your category. Update these pages with comprehensive, current information about your brand.
Rapid Content Updates for Detected Gaps
When monitoring reveals content gaps, create targeted updates within days. Speed matters because competitors fill gaps quickly.
Map detected gaps to content needs. Missing from troubleshooting queries? Publish solution guides. Absent from comparison prompts? Create detailed comparison content. Not mentioned in definitional queries? Build category education resources.
One approach combines Chat Intelligence for cross-platform brand mention tracking with automated content generation. Detect gap, generate content, publish, and re-measure visibility in a continuous loop.
Measurement: Tracking Visibility Improvement
Measure baseline visibility before taking action. Re-measure after content updates to prove impact.
Key metrics include mention rate by prompt category, share of voice versus competitors, and AI Visibility Score trends. Track time-to-inclusion after publishing new content.
Teams can get your AI Visibility Score to establish a quantified baseline and track progress over time.
Multi-Model Coverage Beyond ChatGPT
ChatGPT isn’t the only chat engine prospects use. Your monitoring needs to cover Claude, Gemini, Perplexity, Grok, and Google AI Overviews.
Model-Specific Prompt Nuances
Each chat engine responds differently to identical prompts. Claude favors detailed, nuanced answers. Gemini integrates Google Search results. Perplexity emphasizes citations. Grok adds personality and current events.
Test your prompt bank across all models. Adjust phrasing for models that require different query structures. Track which prompts work consistently versus which need model-specific versions.
Cadence and Concurrency Considerations
Querying five models simultaneously multiplies your monitoring load. Stagger queries to avoid rate limits. Prioritize models based on user adoption in your target markets.
Run high-priority prompts across all models daily. Medium-priority prompts can rotate: ChatGPT Monday, Claude Tuesday, Gemini Wednesday, etc. Low-priority prompts run weekly per model.
Consolidated Reporting Across Engines
Your executive dashboard needs unified visibility across all chat engines. Show mention rate by model, competitive positioning, and share-of-voice trends.
- Overall mention rate: percentage of queries where you appear across all models
- Model-specific performance: which engines favor your brand
- Consistency score: how often all models agree on your inclusion
- Competitive gaps: where competitors dominate specific models
Risk Management When Models Disagree
When ChatGPT recommends your brand but Claude doesn’t, investigate why. Model disagreement signals inconsistent entity understanding or source availability.
Document disagreements. Analyze which sources each model uses. Strengthen weak signals across all models to improve consistency.
Measurement Framework and Reporting
Your monitoring system generates data. Your measurement framework turns data into business intelligence.
Core Metrics for AI Visibility
Track four primary metrics across all prompts and models:
- Mention rate: percentage of queries where your brand appears
- Citation quality: authority and relevance of sources ChatGPT uses
- Share of voice: your mentions versus competitor mentions
- Time-to-detection: how quickly you identify visibility changes
Calculate metrics by prompt category, model, geography, and time period. Trend analysis reveals whether visibility is improving or declining.
Before/After Analysis
When you take action based on detections, measure impact with before/after comparisons. Track mention rate for 30 days before content updates, then 30 days after.
Document what changed: new pages published, entity updates made, citations acquired. Connect actions to visibility improvements. This proves ROI and guides future optimization.
Executive Rollups and Trendlines
Executives need high-level visibility trends, not raw detection logs. Create monthly rollups showing:
- Overall mention rate trend with month-over-month change
- Share-of-voice versus top three competitors
- Geographic performance heatmap with problem markets highlighted
- Top visibility gaps and recommended actions
- Content updates delivered and their measured impact
Include market breakdowns for regions with dedicated teams. Show which markets improved and which declined.
Build vs Buy Considerations
You can build monitoring infrastructure in-house or use a platform. Each approach has distinct tradeoffs.
Engineering Cost and Maintenance Burden
Building in-house requires engineering resources for development, testing, and ongoing maintenance. You need to handle API integrations, rate limiting, error handling, and data storage.
Platform changes break your scripts. OpenAI updates ChatGPT frequently. Each update requires testing and potential code changes. Maintenance becomes a permanent cost.
Localization Scaling and Parallelization
City-level monitoring across dozens of locations requires parallel query execution. Building this infrastructure means managing proxies, handling geolocation, and coordinating concurrent requests.
Platforms handle parallelization automatically. They maintain proxy networks and location infrastructure. You configure what to monitor, not how to execute queries.
Security, Governance, and Compliance
Your monitoring system handles competitive intelligence and customer data. In-house builds need security reviews, access controls, audit logging, and compliance documentation.
Enterprise platforms provide SOC 2 compliance, role-based access control, and audit trails out of the box. This reduces your compliance burden and accelerates deployment.
Time-to-Value and Reliability Tradeoffs
Building takes months. Using a platform takes days. If you need visibility insights quickly to respond to competitive threats, platforms deliver faster time-to-value.
Platforms also provide reliability guarantees, support teams, and regular feature updates. In-house builds require you to solve every problem yourself.
Frequently Asked Questions
Is monitoring ChatGPT responses permitted under OpenAI’s terms of service?
Automated querying must respect rate limits and usage policies. Use API access where available. Avoid excessive scraping that could trigger account restrictions. Document your monitoring practices for compliance reviews. Platforms handle compliance automatically.
How reliable are AI responses across different sessions?
Session variability is significant. The same prompt produces different recommendations across sessions. This is why single-check monitoring fails. You need multiple sessions per prompt to calculate reliable mention rates and understand consistency.
How do I avoid false positives and hallucinations?
Require cross-session confirmation before logging detections. Verify citations actually mention your brand. Implement manual review for sensitive claims. Set confidence thresholds that balance detection sensitivity with accuracy.
What’s the minimum monitoring frequency for actionable insights?
High-priority commercial-intent queries need daily monitoring. Category-defining prompts can run weekly. Adjust frequency based on competitive intensity and market volatility. Increase frequency during product launches or major campaigns.
How long does it take to see visibility improvements after content updates?
Entity updates take two to four weeks to propagate. New content appears in chat engines within days to weeks depending on crawl frequency and authority. Track mention rate changes weekly after publishing updates to measure impact timing.
Can I monitor multiple languages and regions simultaneously?
Yes, but it multiplies monitoring load. Prioritize markets by revenue and risk. Use platforms with built-in localization support to scale efficiently. Start with core markets and expand as you prove ROI.
What should I do when a competitor suddenly dominates recommendations?
Investigate what changed. Check if the competitor published new content, acquired citations, or strengthened entity signals. Review your own content for gaps. Create targeted updates addressing the specific prompts where they gained share. Re-measure within 30 days.
How do I measure return on investment for AI visibility monitoring?
Track mention rate improvement over time. Connect visibility gains to pipeline metrics using attribution. Calculate cost per visibility point gained. Compare monitoring cost to customer acquisition cost for the channel. Platforms typically pay for themselves within quarters through improved brand consideration.
Take Control of Your AI Visibility
You can reliably detect live brand references in ChatGPT with a disciplined monitoring workflow. The architecture is straightforward: prompt bank, session rotation, automated scheduling, structured logging, and real-time alerting.
Localization and session variability must be built into your process from day one. City-level tracking reveals geographic blind spots. Multi-session testing captures consistency. Without these elements, your data misleads more than it informs.
- Alerting and governance turn detections into action without chaos
- Closing the loop with content and entity updates moves mention rates up
- Multi-model coverage ensures you track visibility across all chat engines
- Measurement frameworks prove impact and guide optimization priorities
- Build versus buy decisions depend on engineering capacity and time-to-value needs
With a repeatable workflow, you shift from guessing to proving visibility gains. You know when ChatGPT recommends your brand, when it doesn’t, and why. You detect changes within hours instead of weeks. You close gaps before they cost you deals.
Establish your baseline with an AI visibility assessment. Prioritize markets with the biggest revenue upside. Start monitoring high-value commercial-intent queries first. Expand coverage as you prove impact.
If you need fast, multi-model rollout with city-level precision and automated alerting, explore a monitoring solution that handles logging, localization, and action workflows end-to-end. The alternative is months of engineering work before you see your first detection.