
Search doesn’t rank anymore. It recommends. And those recommendations change from New York to London to Singapore. If your brand isn’t visible in AI Overviews or chat engines across key markets, you’re invisible where decisions start.
Regional gaps compound fast. A strong presence in one city means nothing in another. You can’t fix what you can’t see.
This guide shows you how to monitor AI search trends at city-level precision across engines and languages. You’ll learn to turn visibility gaps into measurable gains using a framework that tracks mentions, citations, and share of voice across Google AI Overviews, ChatGPT, Claude, Gemini, Perplexity, and Grok.
The approach builds on the Intelligence² concept – combining human and artificial intelligence to close the loop from detection to automated action. Let’s start with why regional monitoring matters.
Why City-Level Tracking Beats Country-Level Monitoring
AI recommendations vary dramatically by location. A query in Miami returns different brands than the same query in Seattle. Country-level tracking misses these critical variations.
City-level precision reveals three insights country data hides:
- Local competitor dominance in specific metros
- Regional content gaps affecting visibility
- Language preference patterns within multilingual markets
- Urban vs suburban recommendation differences
- Timezone-based query behavior shifts
Geographic Precision Drives Better Decisions
Consider a global SaaS brand tracking generative search visibility. Country-level data shows strong UK presence. City-level data reveals London dominance but zero visibility in Manchester, Birmingham, and Edinburgh.
That granularity changes your action plan. Instead of generic UK content, you create Manchester-specific case studies and Birmingham partner stories. You monitor AI brand mentions in each city separately to measure impact.
The same principle applies across markets. Tokyo visibility doesn’t predict Osaka performance. Berlin trends don’t match Munich behavior. Track where your customers actually search.
Multi-Language Complexity Multiplies Regional Gaps
Language adds another layer. Canada requires English and French tracking. Switzerland needs German, French, and Italian. UAE demands Arabic and English coverage.
Each language-city combination creates a unique visibility profile:
- Query phrasing differs between languages for identical intent
- AI engines prioritize different sources by language
- Translation quality affects citation likelihood
- Cultural context changes recommendation relevance
- Local domain authority varies by language market
You need multi-language tracking that normalizes data for comparison while preserving local nuances. A mention in English-Canada and French-Canada both count toward national share of voice, but require separate optimization strategies.
Core KPIs for Regional AI Visibility
Traditional SEO metrics don’t translate to AI recommendations. Rankings don’t exist. Click-through rates mean nothing when AI engines synthesize answers without links.
Track these regional insights instead:
- AI Visibility Score – composite metric combining mention frequency, citation quality, and share of voice
- Mention rate – percentage of queries where your brand appears in AI responses
- Citation quality – how prominently and accurately AI engines reference your content
- Share of voice – your mention percentage vs competitors in target queries
- Response position – placement within AI-generated answers (early vs late mention)
AI Visibility Score as Your North Star
The AI Visibility Score consolidates multiple signals into one trackable number. It weighs mention frequency against citation context and competitive presence.
A score of 75 in New York but 23 in London tells you exactly where to focus. The metric works across engines and languages because it normalizes for query volume and market size.
Get your AI Visibility Score to establish your baseline before building a monitoring system.
Share of Voice Reveals Competitive Dynamics
Share of voice measures your brand mentions against competitors in the same query set. If three brands appear in AI responses for “project management software,” and you appear in 40% of those responses while competitors split the remaining 60%, your share of voice is 40%.
Track this metric by city to spot competitive threats early. A competitor gaining share in Austin while you hold steady in San Francisco signals a regional content gap.
Monitor share of voice across these dimensions:
- Branded queries (your brand name)
- Category queries (product/service type)
- Competitor comparison queries
- Problem-solution queries
- Feature-specific queries
Building Your Regional Monitoring Framework
Effective monitoring requires a structured approach. Random spot checks miss patterns. Manual tracking doesn’t scale. You need a repeatable system that captures trends across markets.
The framework has seven components that work together to deliver actionable insights.
Scoping: Define Your Coverage Map
Start by selecting cities, languages, and priority topics. Don’t try to monitor everything. Focus on markets that drive revenue or growth.
Build a coverage matrix with these columns:
- City or metro area
- Primary language
- Secondary languages (if applicable)
- Query volume estimate
- Business priority (high/medium/low)
- Current visibility baseline
For a global brand, this might include 20-30 cities across 10-15 languages. An agency managing multiple clients needs separate matrices per client.
Prioritize cities where you have physical presence, active customers, or expansion plans. Add competitive strongholds where you need to gain ground.
Query Design: Build Intent-Driven Prompt Sets
AI engines respond to natural language queries, not keywords. Your monitoring prompts need to reflect how real users ask questions.
Create query clusters around these intent types:
- Discovery – “what is the best [solution] for [use case]”
- Comparison – “compare [your brand] vs [competitor]”
- Problem-solving – “how to fix [specific problem]”
- Feature evaluation – “does [solution] support [feature]”
- Buying research – “is [brand] worth the cost”
Write 5-10 variations per intent type. Include branded and unbranded versions. Add competitor names to capture comparison contexts.
Test queries in target languages with native speakers. Direct translation often misses colloquialisms and regional phrasing patterns.
Cross-Engine Coverage: Monitor Where Decisions Happen
Users don’t stick to one AI platform. They ask ChatGPT, check Perplexity, and see Google AI Overviews in search results. Your monitoring must cover all channels.
Track these platforms for complete visibility:
- Google AI Overviews – appears in search results for informational queries
- ChatGPT – dominant conversational AI with massive user base
- Claude – growing enterprise adoption for research and analysis
- Gemini – Google’s standalone chat interface
- Perplexity – citation-focused search alternative
- Grok – X integration reaching different user demographic
Each engine has different recommendation logic. Strong ChatGPT presence doesn’t guarantee Google AI Overviews visibility. SERP Intelligence and Chat Intelligence together provide unified coverage across both search and chat contexts.
Data Capture: Collect Context Beyond Mentions
A simple mention count misses critical context. You need to capture how AI engines reference your brand, not just that they do.
Record these data points for each query response:
- Brand mentioned (yes/no)
- Citation included (yes/no with source URL)
- Mention position (early/middle/late in response)
- Sentiment context (positive/neutral/negative framing)
- Competitor co-mentions
- Response length and detail level
- Source attribution quality
This granular data reveals patterns that aggregate metrics hide. You might have high mention rates but consistently appear last in recommendations. Or get mentioned often but rarely cited with links.
Normalization: Make Regional Data Comparable
Raw data from different markets isn’t directly comparable. Query volume varies by city size. Language differences affect response patterns. You need normalization to spot true trends.
Apply these normalization techniques:
- Index mention rates to query volume baselines
- Weight share of voice by market size
- Adjust for language-specific response lengths
- Control for seasonal and event-driven spikes
- Factor in local competitor density
A 30% mention rate in Singapore (population 5.9M) carries different weight than 30% in New York (population 8.3M). Normalize to population, GDP, or industry concentration depending on your business model.
Quality Control: Human + AI Intelligence
Automated monitoring catches volume but misses nuance. AI engines sometimes hallucinate brand mentions. They conflate similar company names. They misattribute sources.
The Intelligence² approach combines automated detection with human verification:
- AI workers query engines at scale (150 parallel workers for real-time coverage)
- Automated parsing extracts mentions and citations
- Human reviewers validate ambiguous cases
- Feedback loop trains detection accuracy over time
- Exception handling for new mention patterns
This hybrid model delivers speed and precision. You get real-time alerts when visibility drops in a market, with confidence the signal is accurate.
Cadence: Establish Monitoring Rhythms
Different metrics need different monitoring frequencies. Share of voice changes slowly. Specific query responses can shift overnight.
Set up these monitoring cadences:
- Real-time alerts – major visibility drops or competitor surges
- Daily checks – high-priority branded queries and top competitors
- Weekly analysis – full query set across all cities and languages
- Monthly trends – share of voice changes and new competitor patterns
- Quarterly reviews – coverage map updates and strategy adjustments
Balance monitoring depth against team capacity. Start with weekly city-level checks and expand as you build workflows.
Turning Insights Into Automated Actions
Monitoring without action wastes resources. The goal isn’t data collection. The goal is closing visibility gaps faster than competitors.
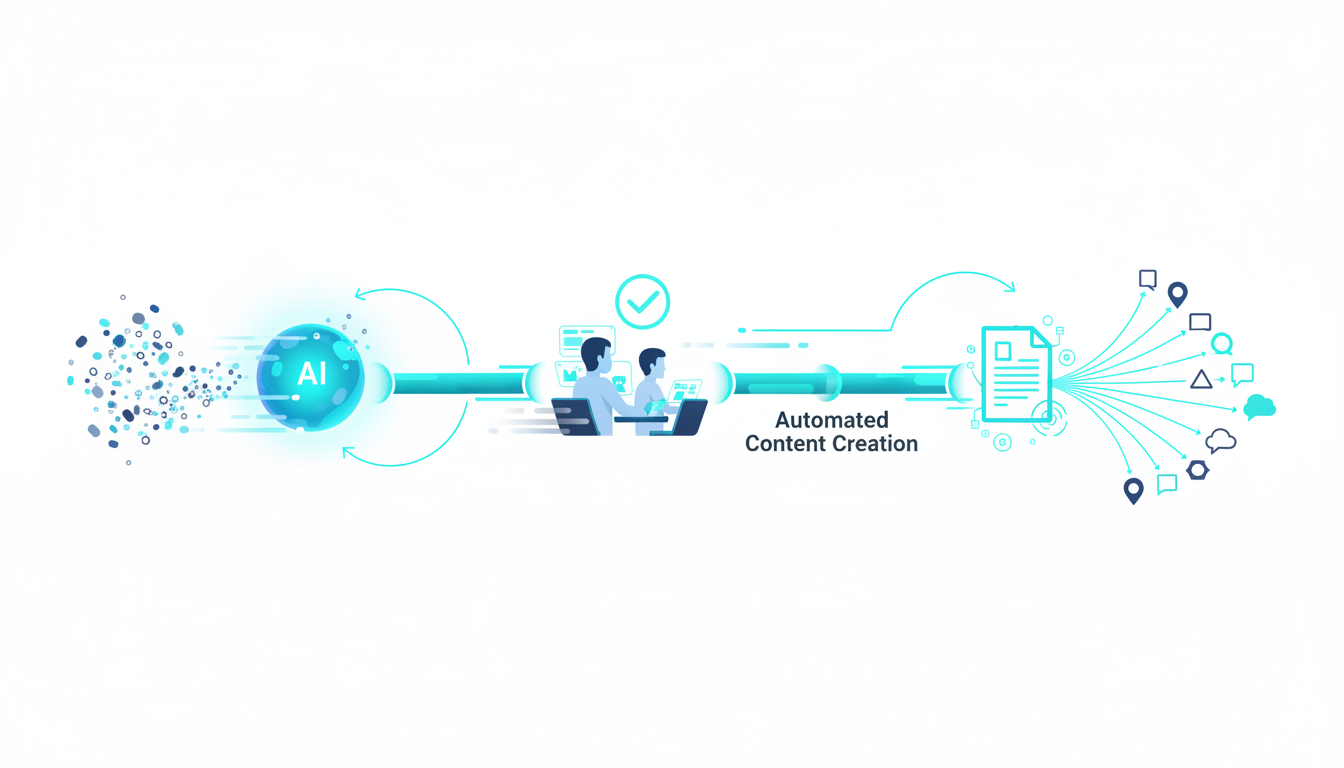
The action loop connects detection to optimization in seven steps: Monitor → Analyze → Create → Publish → Amplify → Measure → Optimize.
From Gap Detection to Content Creation
When monitoring reveals a visibility gap, the system should trigger content creation automatically. A drop in Chicago mentions for “enterprise collaboration tools” becomes a content brief for Chicago-focused case studies.
The Content & Action Engine automates this workflow:
- Gap detection identifies missing coverage
- Analysis determines root cause (content gap vs citation gap vs authority gap)
- Content briefs generate with city-specific requirements
- Creation combines AI drafting with human editing
- Publishing distributes to owned channels
- Amplification seeds content to citation sources
- Measurement tracks visibility changes
- Optimization refines based on results
This cycle completes in 10-15 minutes from detection to publication. Speed matters because AI engine recommendations update constantly.
Prioritization: Where to Act First
You can’t close every gap simultaneously. Prioritize based on impact and effort.
Map opportunities on a two-by-two grid:
- High impact, low effort – act immediately (quick wins)
- High impact, high effort – plan carefully (strategic projects)
- Low impact, low effort – batch process (efficiency plays)
- Low impact, high effort – defer or skip (poor ROI)
Impact measures potential visibility gain. Effort estimates content creation and citation building required. A city where you already have strong traditional SEO but weak AI presence is high impact, low effort. A new market with no existing content is high effort regardless of impact.
Regional Content Strategies That Work
Generic content doesn’t win regional visibility. AI engines prioritize locally relevant sources and examples.
Build regional content around these angles:
- City-specific case studies and customer stories
- Local industry trends and statistics
- Regional compliance and regulatory considerations
- Area-specific use cases and applications
- Local partner and integration ecosystems
- Geographic pricing and availability details
A cybersecurity vendor targeting Munich needs content about German data protection laws, local enterprise customer examples, and EU compliance frameworks. The same vendor targeting Singapore needs different angles around APAC regulations and regional threat landscapes.
Scaling Multi-Market Monitoring Operations
Monitoring one city in one language is straightforward. Monitoring 30 cities in 15 languages requires operational discipline.
Scale your monitoring without losing quality by following these principles.
Governance: Localization and Translation Workflows
Content must be locally relevant, not just translated. Direct translation misses cultural context and market-specific needs.
Establish these governance layers:
- Central strategy – global query frameworks and KPI definitions
- Regional adaptation – market-specific query variations and priorities
- Local validation – native speaker review of translations and context
- Quality assurance – cross-market consistency checks
- Continuous improvement – feedback loops from regional teams
A global team sets the monitoring framework. Regional managers adapt queries and content angles. Local contributors validate language and cultural fit. This three-tier model balances consistency and relevance.
Reporting: Executive vs Practitioner Views
Different stakeholders need different reporting depths. Executives want trends and business impact. Practitioners need query-level details and optimization recommendations.
Build two reporting tracks:
Watch this video about monitoring ai search trends for specific regions:
- Executive dashboards – AI Visibility Score trends by region, share of voice changes, competitive movements, ROI metrics
- Practitioner reports – query-level performance, content gap lists, optimization task queues, A/B test results
Update executive views monthly. Refresh practitioner dashboards daily or weekly depending on monitoring cadence.
Include these elements in executive reports:
- Geographic heatmap showing visibility by city
- Trend lines for top 5 markets
- Competitive share of voice comparison
- Content actions taken and impact measured
- Strategic recommendations for next quarter
White-Label Scaling for Agency Partners
Agencies managing multiple clients need efficient multi-tenant monitoring. Building separate systems for each client doesn’t scale.
A white-label platform approach solves this by providing:
- Client-specific dashboards with custom branding
- Isolated data environments for client confidentiality
- Shared infrastructure for cost efficiency
- Centralized reporting across client portfolio
- Per-client billing and usage tracking
This model lets agencies offer sophisticated regional monitoring without building technology in-house. Focus stays on strategy and client relationships while the platform handles execution.
Common Failure Modes and How to Avoid Them

Regional monitoring projects fail in predictable ways. Recognize these patterns early to course-correct.
Failure Mode: Keyword Thinking in an AI World
Many teams start by monitoring traditional keywords. AI engines don’t work that way. They respond to natural questions and synthesize answers from multiple sources.
Shift from keywords to intent clusters. Instead of tracking “project management software,” monitor these queries:
- “What’s the best way to manage remote team projects?”
- “How do I track project deadlines across multiple teams?”
- “Compare Asana vs Monday vs Clickup for marketing teams”
- “Does [your product] integrate with Slack and Teams?”
These natural language queries reveal how AI engines actually recommend solutions.
Failure Mode: Monitoring Without Action Triggers
Collecting data feels productive. But data without decisions is waste. Set clear action triggers before you start monitoring.
Define thresholds that trigger responses:
- AI Visibility Score drops 15+ points in a market → investigate cause within 24 hours
- Competitor share of voice increases 10+ points → analyze their new content within 48 hours
- Zero mentions in a priority city for 2+ weeks → create city-specific content within 1 week
- Citation quality drops (links removed) → contact sources and offer updated content
These rules convert monitoring signals into concrete tasks. Your team knows exactly what to do when metrics change.
Failure Mode: Ignoring Language Nuance
Machine translation handles literal meaning but misses context. A query that works in English might sound unnatural in Spanish or awkward in Japanese.
Work with native speakers to craft queries that sound natural in each language. Test responses to verify AI engines understand intent correctly.
Budget time for this linguistic validation. It’s the difference between monitoring what you think users ask and what they actually ask.
Failure Mode: Over-Monitoring Low-Value Markets
Comprehensive coverage sounds ideal but wastes resources. Not every city deserves equal attention.
Apply the 80/20 rule. Identify the 20% of cities that drive 80% of business value. Monitor those intensively. Check other markets monthly or quarterly.
Adjust coverage as business priorities shift. An expansion into Latin America means increasing monitoring frequency in São Paulo, Mexico City, and Buenos Aires while reducing coverage in mature markets.
Implementation Templates and Checklists
Theory helps. Templates accelerate execution. Use these frameworks to launch your regional monitoring program.
Market-Language Coverage Matrix
This spreadsheet template organizes your monitoring scope:
- Column A: City/Metro Area
- Column B: Country
- Column C: Primary Language
- Column D: Secondary Languages
- Column E: Business Priority (1-5 scale)
- Column F: Current AI Visibility Score
- Column G: Monitoring Frequency
- Column H: Assigned Owner
- Column I: Last Review Date
- Column J: Next Action
Fill this matrix before building query sets. It becomes your master reference for coverage decisions.
KPI Dictionary and Baseline Worksheet
Define metrics before you start measuring. This prevents confusion when comparing data across markets.
Your KPI dictionary should include:
- Metric name – standardized term used in all reports
- Definition – precise calculation method
- Normalization – how to adjust for market size
- Target range – good/acceptable/poor thresholds
- Action trigger – when to respond to changes
- Update frequency – how often to recalculate
Example entry for AI Visibility Score:
- Definition: Composite of mention rate (40%), citation quality (35%), and share of voice (25%)
- Normalization: Indexed to market query volume and competitor density
- Target range: 70+ excellent, 50-69 good, 30-49 acceptable, below 30 poor
- Action trigger: 15-point drop in any market within 30 days
- Update frequency: Weekly for priority markets, monthly for others
Query Set Template by Intent Type
Organize queries into intent clusters for systematic coverage. This template structures your monitoring prompts:
Discovery Intent Queries:
- “What is the best [solution category] for [use case]?”
- “Top [solution category] for [industry/role]”
- “How to choose [solution category]”
- “[Solution category] comparison guide”
- “Best [solution category] in [city/region]”
Comparison Intent Queries:
- “Compare [your brand] vs [competitor A]”
- “[Your brand] or [competitor B] for [use case]”
- “Differences between [your brand] and [competitor C]”
- “Is [your brand] better than [competitor D]”
- “[Competitor E] alternatives”
Create similar clusters for problem-solving, feature evaluation, and buying research intents. Aim for 5-8 queries per intent type per market.
Regional Content Gap Analysis Framework
When monitoring reveals weak visibility in a market, this framework diagnoses the root cause:
- Content existence – Do you have any content relevant to this market?
- Content quality – Is existing content comprehensive and current?
- Local relevance – Does content include city-specific examples and data?
- Citation sources – Are you linked from authoritative local sources?
- Language optimization – Is content in native language with proper localization?
- Technical accessibility – Can AI engines access and parse your content?
Score each dimension 1-5. Low scores indicate where to focus optimization efforts. A market with strong content but weak citations needs outreach, not more writing.
Measuring Success and Proving ROI
Regional monitoring requires investment. Stakeholders want proof it drives business results.
Track these metrics to demonstrate value:
- Visibility gains – AI Visibility Score improvements by market
- Share of voice growth – competitive position changes
- Content efficiency – time from gap detection to published content
- Citation acquisition – new authoritative sources linking to content
- Traffic attribution – visits from AI engine referrals
- Pipeline influence – deals where prospects mentioned AI research
Attribution Challenges in AI Search
AI engines rarely send direct traffic. Users read synthesized answers without clicking sources. Traditional analytics miss this influence.
Use these proxy metrics instead:
- Brand search volume changes after visibility improvements
- Survey data asking prospects how they discovered you
- Sales team feedback on customer research patterns
- Correlation between AI visibility and pipeline velocity
- Competitive win rates in markets with strong AI presence
Build a business case that connects AI visibility to downstream outcomes. A 30-point AI Visibility Score increase in Boston correlates with 15% more inbound leads from that market over the next quarter.
Continuous Optimization Based on Results
Your first monitoring setup won’t be perfect. Refine based on what you learn.
Review these elements quarterly:
- Query sets – remove low-signal queries, add emerging patterns
- Market priorities – shift coverage to growing markets
- KPI thresholds – adjust targets as baseline visibility improves
- Action triggers – tune sensitivity to reduce false alerts
- Content templates – optimize based on what drives citations
Monitoring should get more efficient over time as you learn which signals predict business impact.
The Future of Regional AI Monitoring
AI search behavior evolves rapidly. Your monitoring system must adapt to stay relevant.
Watch these emerging trends:
- Hyper-local recommendations – AI engines incorporating neighborhood-level data
- Real-time context – recommendations changing based on current events and trends
- Multimodal search – image and voice queries requiring different monitoring approaches
- Personalization depth – recommendations varying by user history and preferences
- Cross-platform synthesis – AI engines pulling from social media and review platforms
Build flexibility into your monitoring framework. The cities, languages, and engines you track today will expand. The KPIs that matter will evolve. Design systems that accommodate change without requiring rebuilds.
Frequently Asked Questions
How many cities should I monitor to start?
Begin with 5-10 cities that represent your largest markets or highest growth opportunities. Expand coverage as you build operational capacity and prove ROI. Focus beats breadth when starting.
What’s the minimum monitoring frequency for useful insights?
Weekly monitoring captures meaningful trends without overwhelming your team. Daily checks make sense only for high-priority branded queries or during active campaigns. Monthly is too infrequent to catch competitive movements.
Can I monitor AI visibility without expensive tools?
Manual spot-checking works for very small scale but doesn’t scale beyond 2-3 markets. The time cost exceeds tool cost quickly. Basic monitoring needs at least query automation and data aggregation. See the platform for complete automation options.
How do I handle privacy and compliance in regional monitoring?
Monitor only public AI engine responses. Don’t attempt to track individual user queries. Store only aggregated metrics, not raw query logs. Follow data residency requirements for markets with strict regulations like EU and China.
What’s the typical timeline to see visibility improvements?
Content changes can affect AI recommendations within days, but meaningful share of voice shifts take 4-8 weeks. Plan for 90-day measurement cycles to assess strategy effectiveness. Quick wins happen in underserved markets with weak competition.
How do I coordinate monitoring across multiple teams or agencies?
Centralize your monitoring platform and reporting. Use a shared KPI dictionary and coverage matrix. Assign clear market ownership to prevent gaps and overlaps. Schedule weekly syncs to review trends and coordinate actions across regions.
Take Action on Regional AI Visibility
You now have a complete framework for monitoring AI search trends across cities, languages, and engines. The key insights:
- AI recommendations vary dramatically by location – track at city level
- Measure what matters: mentions, citations, share of voice, and AI Visibility Score
- Close the loop from detection to automated content creation and publishing
- Monitor across all major engines to avoid blind spots
- Build operational discipline with templates and governance
Regional visibility gaps compound into lost opportunities. Every day without monitoring is another day competitors claim recommendations in your target markets.
Start with baseline measurement. Get your AI Visibility Score to see where you stand today across markets. Then build your coverage matrix and query sets using the templates in this guide.
The brands winning in AI search aren’t guessing. They’re measuring, optimizing, and iterating faster than competition. Your regional monitoring system is the foundation for that advantage.