
Search engines don’t rank pages anymore. They recommend brands. When someone asks ChatGPT for accounting software or Google serves an AI Overview about project management tools, your brand either appears in that answer or it doesn’t.
That’s AI-driven brand visibility. It’s not about position 1 versus position 3. It’s about being mentioned, cited, or recommended when AI systems answer questions in your category.
Traditional SEO metrics can’t measure this. You need new frameworks built for a world where AI systems decide which brands to surface. Before evaluating any platform, you need to understand what you’re actually measuring.
The Four Pillars of AI Visibility
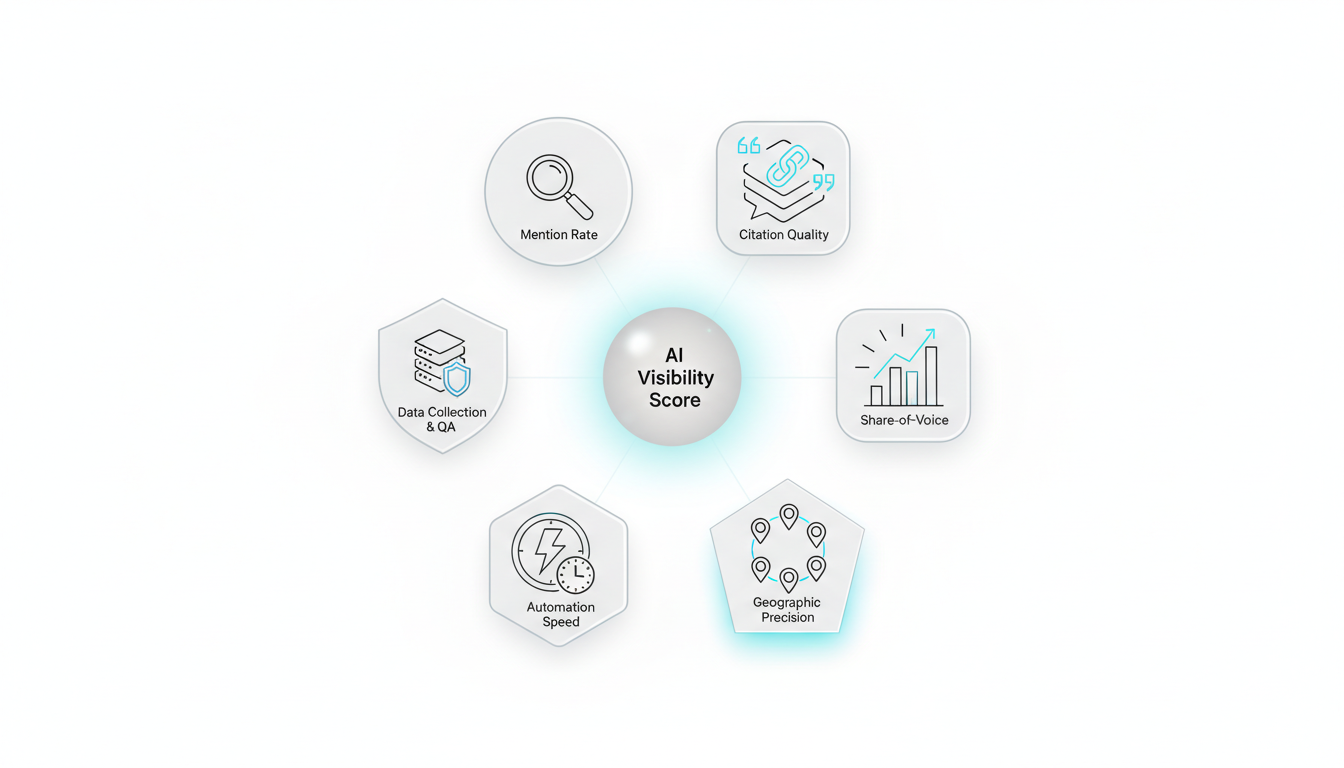
AI visibility breaks down into four distinct measurement areas. Each requires different tracking approaches and reveals different competitive insights.
- Mention rate – How often your brand appears when AI systems answer relevant queries
- Citation quality – Whether mentions include context, links, or substantive descriptions
- Visibility share – Your brand’s prominence compared to competitors in the same answer
- Geographic precision – How visibility varies across cities, regions, and languages
A brand might have high mention rates but poor citation quality. Another might dominate in English but disappear in Spanish. These nuances matter when you’re allocating budget or justifying platform investments.
Where AI Visibility Lives
AI-driven visibility appears in two distinct environments. Each has different data structures, update frequencies, and optimization requirements.
SERP Intelligence tracks AI Overviews in Google search results. These appear above traditional organic listings and synthesize information from multiple sources. They update frequently but follow Google’s indexing patterns.
Chat Intelligence monitors recommendations in conversational AI platforms. This includes ChatGPT, Claude, Gemini, Perplexity, and Grok. These systems query in real-time and can produce different answers for identical questions asked minutes apart.
Most teams focus on one or the other. That creates blind spots. A brand might dominate AI Overviews but never appear in ChatGPT recommendations. You need visibility across both environments to understand your complete AI presence.
Why Geographic Tracking Changes Everything
AI systems serve different answers based on user location. A query about “best CRM software” from Austin produces different results than the same query from Boston.
Country-level tracking misses these variations. You need city-level precision to understand how AI systems treat your brand across different markets. This matters for multi-location businesses, franchises, and brands with regional competitors.
Language adds another layer. AI systems trained on English content often struggle with other languages. Your brand might appear consistently in English queries but vanish in French or Spanish variations of the same question.
The Evaluation Framework: Six Core Criteria
Evaluating AI visibility platforms requires standardized criteria. These six metrics create an objective comparison framework that works across any solution.
Mention Rate Measurement
Mention rate calculates how often your brand appears when AI systems answer category-relevant queries. The formula is straightforward but requires consistent query sampling.
Mention Rate = (Queries With Brand Mention / Total Queries Tested) × 100
- Test minimum 100 queries per category per month
- Include branded, category, and competitor comparison queries
- Track separately for SERP and chat environments
- Measure across different geographic markets
- Monitor language variations independently
A platform claiming to improve mention rates should show baseline measurements, tracking over time, and statistical significance of any changes. Without this data trail, you’re making decisions blind.
Citation Quality Scoring
Not all mentions carry equal weight. A passing reference differs from a detailed recommendation with supporting context and a clickable link.
Citation quality uses a weighted scoring system:
- Basic mention – Brand name appears (1 point)
- Contextual mention – Includes category or use case (2 points)
- Descriptive citation – Adds features, benefits, or differentiators (3 points)
- Linked citation – Includes clickable URL to your site (4 points)
- Recommended citation – Explicitly recommends your brand (5 points)
Average these scores across all mentions to get your Citation Quality Index. A brand with 50 basic mentions and a CQI of 1.2 has weaker visibility than a brand with 30 mentions and a CQI of 3.8.
Share of Voice in AI Answers
Share of voice measures your brand’s prominence relative to competitors when multiple brands appear in the same AI answer.
Calculate this by tracking mention position and context weight. The first brand mentioned typically receives more attention than brands listed later. Brands with detailed descriptions carry more weight than those in simple lists.
- Position 1 mention = 100% base score
- Position 2 mention = 70% base score
- Position 3 mention = 50% base score
- Position 4+ mention = 30% base score
Multiply base scores by citation quality weights. Sum your weighted scores and divide by total weighted scores for all brands in the answer. This gives you percentage share of voice for that specific query.
Geographic Coverage and Precision
Geographic tracking separates basic platforms from enterprise solutions. Country-level tracking misses critical market variations.
Evaluate platforms on these geographic capabilities:
- City-level tracking – Can the platform test from specific cities, not just countries?
- Coverage breadth – How many countries and cities can you monitor?
- Language flexibility – Can you test any language in any location?
- Sampling density – How many data points per city per time period?
- Update frequency – How often does location data refresh?
A platform offering 195+ countries with city-level precision in unlimited languages provides fundamentally different insights than one limited to major metro areas in English-speaking countries.
Automation Speed and Reliability
Monitoring alone doesn’t improve visibility. You need to close gaps between current performance and target outcomes. Automation speed determines how quickly you can act on insights.
Measure these automation capabilities:
- Detection to action time – How long from identifying a gap to creating corrective content?
- Publishing automation – Can the platform publish content automatically or require manual intervention?
- Optimization loops – Does it measure results and iterate automatically?
- Parallel processing – How many queries can it test simultaneously?
- Error handling – What happens when API calls fail or data is incomplete?
A platform completing the full cycle from detection to publishing in 10-15 minutes enables daily optimization sprints. One requiring 24-48 hours for each iteration limits your ability to respond to competitive threats or algorithm changes.
Data Collection Methodology and QA
Garbage in, garbage out. Your evaluation framework only works if the underlying data is accurate and consistent.
Verify these methodology elements:
- How does the platform query AI systems? (API, browser automation, hybrid)
- What quality checks prevent false positives or missed mentions?
- How does it handle rate limits and API restrictions?
- What’s the sample size for statistical significance?
- How are edge cases and ambiguous mentions classified?
Platforms using 150 parallel workers to query AI systems in real-time provide fresher data than those relying on cached results or limited API quotas. Ask for methodology documentation before committing to any solution.
Applying the Framework: Refinea Case Analysis
Now apply these six criteria to evaluate Refinea’s approach to AI-driven brand visibility. This analysis uses publicly available information and industry benchmarks.
Refinea’s Core Measurement Approach
Refinea positions itself as a complete AI visibility platform combining SERP Intelligence and Chat Intelligence in a unified dashboard. The platform tracks brand mentions across Google AI Overviews and five major chat engines.
The Intelligence² concept frames the platform as combining human strategic input with AI-powered automation. This positioning differentiates it from point solutions focused on monitoring alone.
- Unified tracking across SERP and chat environments
- City-level geographic precision in 195+ countries
- Unlimited language combinations for testing
- Real-time querying with 150 parallel workers
- Automated content creation and publishing
These capabilities address the six evaluation criteria. But claims require validation through controlled testing.
Mention Rate Tracking Capabilities
Refinea’s architecture enables high-frequency mention rate tracking. The platform can test hundreds of queries daily across multiple AI systems and geographic markets.
The AI Visibility Score provides a normalized metric for comparing mention rates across different categories, competitors, and time periods. This standardization helps agencies report to clients and enterprises benchmark across business units. Get a quick read with the AI Visibility Score.
Key mention rate features include:
- Baseline measurement across SERP and chat engines
- Trend tracking with customizable time windows
- Competitor comparison for share of mentions
- Geographic breakdown by city or region
- Language-specific mention rates
The platform’s 150 parallel workers enable real-time testing rather than relying on cached or delayed results. This matters when AI systems update frequently or when testing time-sensitive queries.
Citation Quality and Context Analysis
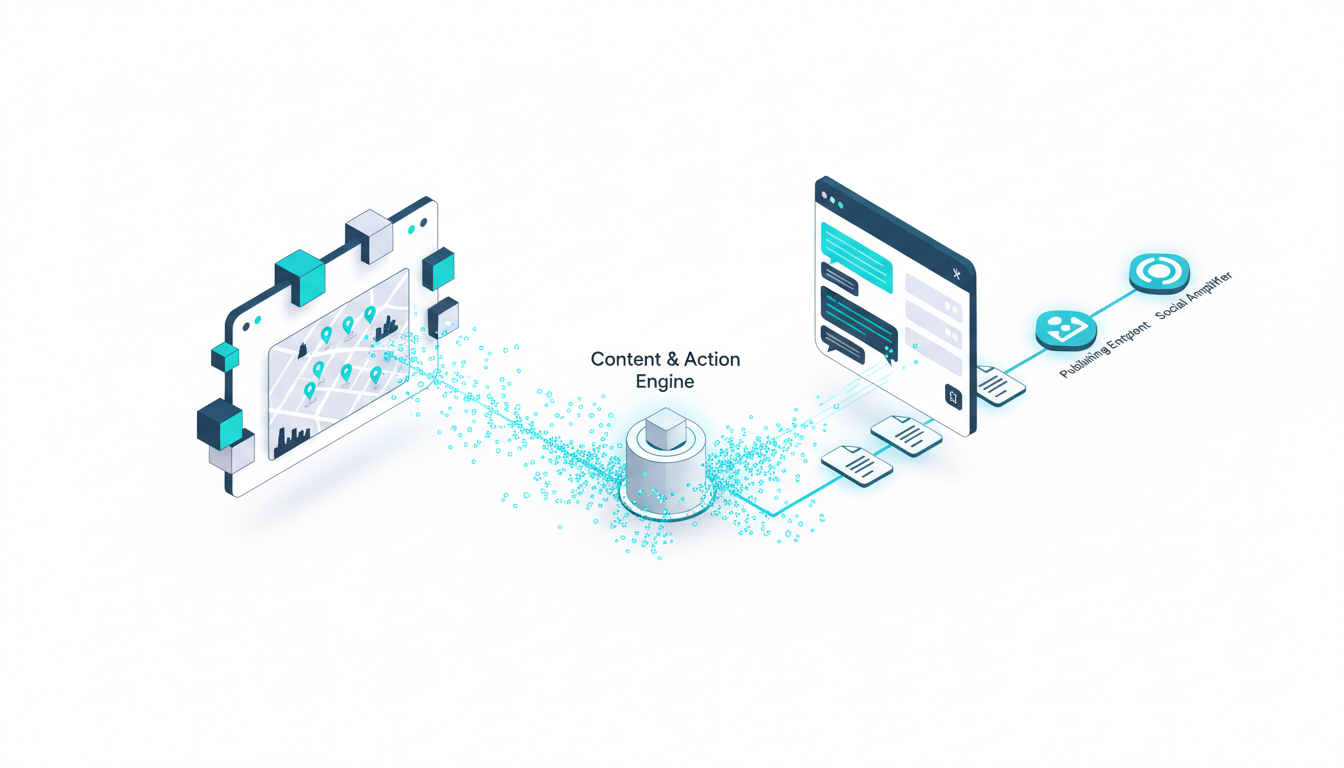
Refinea tracks citation quality through its Content & Action Engine. This component analyzes not just whether your brand appears, but how it’s presented and contextualized.
The platform identifies gaps where competitors receive richer citations or more favorable positioning. It then generates content designed to improve citation quality in future AI answers.
- Automated detection of citation quality differences
- Competitor citation benchmarking
- Gap analysis highlighting missing context or weak descriptions
- Content recommendations to improve citation richness
- Measurement of citation quality changes over time
This goes beyond simple mention tracking. The platform attempts to improve the quality of mentions through automated content optimization.
Geographic Precision and Language Coverage
City-level tracking represents a significant differentiator. Most AI visibility tools operate at country level, missing regional variations that matter for multi-location brands.
Refinea’s geographic capabilities include:
- 195+ countries with city-level precision in major markets
- Unlimited language combinations – test any language in any location
- Regional visibility maps showing performance by geography
- Localized content recommendations based on regional gaps
- Multi-market reporting for agencies managing global clients
For franchises, multi-location businesses, or brands with regional competitors, this geographic precision reveals opportunities invisible in country-level data.
Automation and Optimization Loop
Refinea’s most distinctive feature is the complete automation loop from detection to publishing. The platform claims to close visibility gaps in 10-15 minutes.
The automation sequence works like this:
- Monitor – Track mentions across SERP and chat engines
- Analyze – Identify gaps where competitors appear but you don’t
- Create – Generate optimized content addressing those gaps
- Publish – Deploy content to your site automatically
- Amplify – Distribute through social and other channels
- Measure – Track visibility changes after content goes live
- Optimize – Iterate based on results
This end-to-end automation separates Refinea from monitoring-only tools. Instead of generating reports for humans to act on, it closes the loop automatically.
Strengths in the Evaluation Framework
Applying the six-criteria framework reveals several areas where Refinea performs well relative to alternative approaches.
- Unified SERP + Chat Intelligence – Most tools focus on one or the other
- City-level geographic precision – Rare in the market
- Complete automation loop – Goes beyond monitoring to action
- Real-time querying – 150 parallel workers for fresh data
- White-label partnerships – Revenue share model for agencies
These capabilities address real pain points for SEO professionals transitioning to AI-driven search optimization. The platform provides answers to questions traditional tools can’t address.
Risks and Unknowns to Verify
No platform evaluation is complete without identifying risks and areas requiring validation through hands-on testing.
Key questions to answer during a trial period:
- How accurate is mention detection across different AI systems?
- What’s the false positive rate for brand mentions?
- How does content quality from the Content & Action Engine compare to human-written content?
- What’s the actual time from gap detection to published content in your workflow?
- How does the platform handle edge cases or ambiguous mentions?
- What happens when API rate limits are hit or systems are unavailable?
Run controlled tests comparing Refinea’s data against manual checks. Verify that automated content meets your quality standards. Measure actual cycle times in your environment, not theoretical capabilities.
Alternative Solution Patterns
Refinea represents one approach to AI visibility monitoring and optimization. Understanding alternative patterns helps you make informed build-versus-buy decisions.
Point Solution Assembly
Some teams assemble multiple point solutions, each handling one piece of the visibility puzzle. This might include separate tools for SERP monitoring, chat engine testing, content creation, and publishing.
Advantages of this approach:
- Choose best-in-class tools for each function
- Lower upfront commitment than enterprise platforms
- Flexibility to swap tools as needs change
- Often cheaper for small-scale testing
Disadvantages include:
- Manual integration between tools creates friction
- No unified reporting or single source of truth
- Difficult to automate end-to-end workflows
- Data consistency issues across platforms
- Higher operational overhead managing multiple vendors
Point solution assembly works for teams with strong technical resources who can build integration layers. It struggles when you need speed or scale.
In-House Development
Large enterprises sometimes build custom AI visibility monitoring systems. This requires significant engineering resources but offers maximum control and customization.
Building in-house makes sense when:
- You have unique data requirements no platform addresses
- Engineering resources are available and not constrained
- Long-term cost of ownership favors build over buy
- Proprietary algorithms provide competitive advantage
- Integration with internal systems is critical
The hidden costs of in-house development include ongoing maintenance, keeping pace with AI platform changes, handling API deprecations, and scaling infrastructure. Many teams underestimate these costs.
Hybrid Approaches
Hybrid solutions combine platform capabilities with custom development. You might use a platform for data collection but build custom reporting, or use platform APIs to feed internal systems.
This approach balances speed to market with customization. You get immediate value from platform features while extending capabilities for unique requirements.
- Use platform APIs for data collection and storage
- Build custom dashboards on top of platform data
- Integrate platform insights into existing workflows
- Extend automation with custom business logic
Hybrid approaches require platforms with robust APIs and data export capabilities. Evaluate API documentation and rate limits before committing to this path.
Agency White-Label Programs
Digital marketing agencies face different requirements than in-house teams. They need multi-tenant reporting, client-specific branding, and revenue models that scale with client growth.
Refinea’s white-label program offers 60-70% revenue share, allowing agencies to resell the platform under their own brand. This creates a recurring revenue stream without building the technology.
Other platforms offer similar partnership models with different terms. Compare these factors:
- Revenue share percentage and payment terms
- Branding flexibility and customization options
- Multi-tenant architecture and client isolation
- Onboarding support and training resources
- Minimum commitments or volume requirements
For agencies managing 10+ clients, white-label programs often provide better economics than building custom solutions or assembling point tools for each client.
Watch this video about evaluate refinea on ai-driven brand visibility:
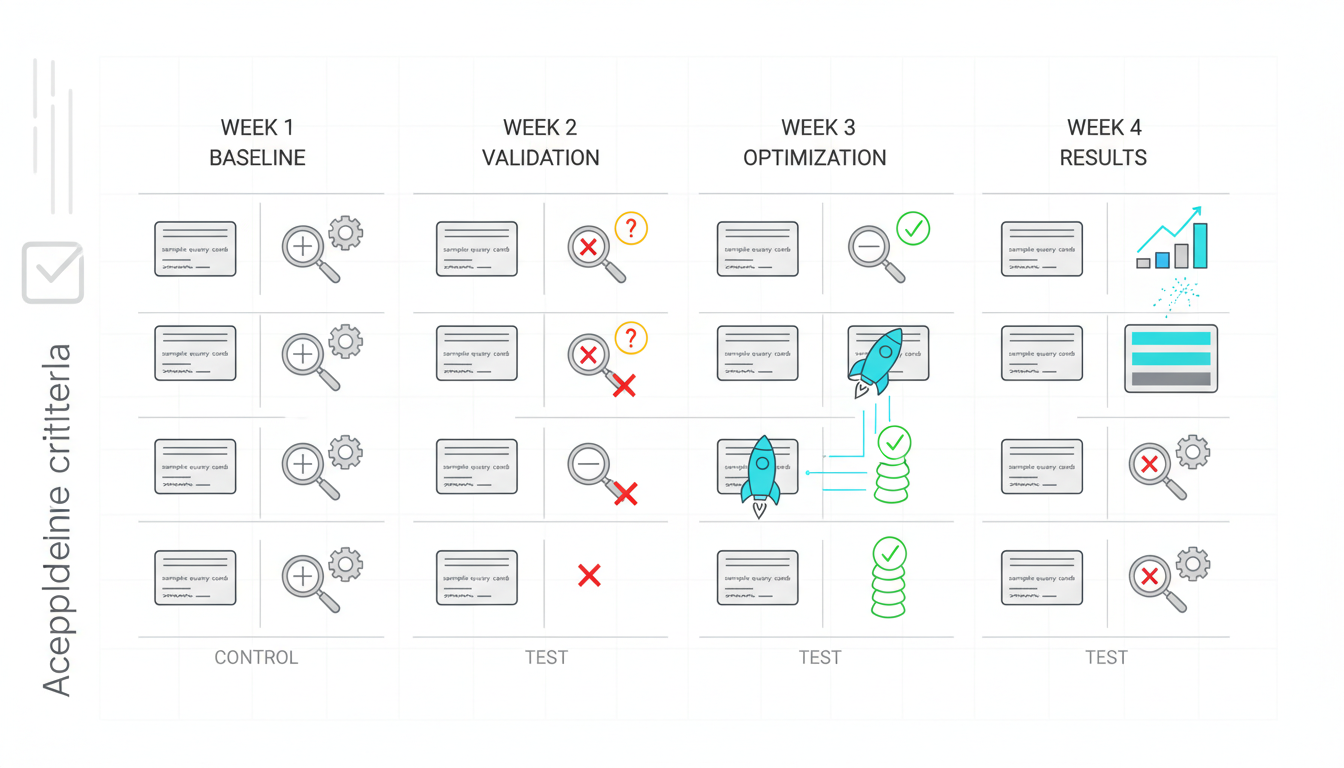
Running a 30-Day Controlled Evaluation
Theory and marketing claims matter less than empirical results. Use this 30-day evaluation protocol to test any AI visibility platform objectively.
Week 1: Baseline Measurement
Start by establishing baseline metrics before implementing any platform. This gives you a control group for measuring actual impact.
Day 1-2 activities:
- Define 50-100 test queries across your category
- Include branded, category, and competitor comparison queries
- Select 5-10 cities representing key markets
- Choose 2-3 languages if you operate internationally
- Document current manual monitoring processes and time requirements
Day 3-5 activities:
- Manually test all queries across Google AI Overviews and chat engines
- Record mention rate, citation quality, and share of voice for each query
- Document time required for manual testing
- Identify top 10 visibility gaps where competitors appear but you don’t
- Calculate baseline AI Visibility Score using the framework above
Day 6-7 activities:
- Set up platform account and configure monitoring
- Import test queries and configure geographic/language settings
- Run initial platform scans and compare results to manual baseline
- Document any discrepancies between platform data and manual checks
- Establish acceptance criteria for data accuracy (target: 95%+ match rate)
Week 2: Data Accuracy Validation
Week 2 focuses on validating the platform’s data collection accuracy. Don’t move forward with optimization until you trust the underlying data.
Daily validation tasks:
- Randomly sample 10-20 queries for manual verification
- Compare platform results to manual checks
- Document false positives (platform shows mention but none exists)
- Document false negatives (platform misses actual mentions)
- Track data freshness – how quickly do platform results reflect AI system changes?
Calculate accuracy metrics:
- Precision – True positives / (True positives + False positives)
- Recall – True positives / (True positives + False negatives)
- F1 Score – 2 x (Precision x Recall) / (Precision + Recall)
Require F1 Score above 0.90 before proceeding to optimization testing. Lower accuracy means you’ll optimize based on flawed data.
Week 3: Automation and Optimization Testing
With validated data collection, test the platform’s optimization capabilities. Focus on measurable improvements in your top 10 visibility gaps.
Select 5 gaps for optimization testing:
- Choose queries where competitors consistently appear but you don’t
- Prioritize queries with commercial intent and search volume
- Select gaps the platform identifies as addressable through content
- Document current mention rate, citation quality, and share of voice
- Set improvement targets (example: 0% to 40% mention rate)
Run optimization experiments:
- Use platform recommendations to create or optimize content
- Track time from gap identification to published content
- Measure actual cycle time versus platform claims
- Document any manual intervention required in the automation loop
- Test content quality – does automated content meet your standards?
Keep 5 gaps as controls – don’t optimize these. Compare results between optimized and control groups to isolate platform impact.
Week 4: Results Measurement and Decision Framework
The final week focuses on measuring results and making a go/no-go decision based on objective criteria.
Measure these outcomes:
- Mention rate improvement – Did optimized queries show measurable gains?
- Citation quality changes – Did the quality of mentions improve?
- Time savings – How much faster is platform monitoring versus manual?
- Automation reliability – What percentage of optimization cycles completed without manual intervention?
- Data accuracy – Did accuracy remain above 90% threshold?
Use this decision matrix:
| Metric | Minimum Acceptable | Target |
|---|---|---|
| Data accuracy (F1 Score) | 0.90 | 0.95 |
| Mention rate improvement | +15% | +25% |
| Time savings vs manual | 50% | 75% |
| Automation success rate | 80% | 90% |
| ROI at 12 months | Break-even | 2x |
Proceed with full implementation only if the platform meets minimum acceptable thresholds on all metrics. One strong metric doesn’t compensate for failure in critical areas like data accuracy.
Implementation Playbooks by Organization Type
Implementation approaches vary based on organization size, resources, and goals. These playbooks provide starting points for different scenarios.
In-House SEO Team Playbook
In-house teams typically start with focused use cases before expanding to full platform adoption.
Phase 1 – Pilot (Months 1-2):
- Select 2-3 high-priority product categories or service lines
- Configure monitoring for 100-200 core queries
- Focus on markets where you have existing content and SEO investment
- Establish baseline metrics and set improvement targets
- Run initial optimization experiments on top visibility gaps
Phase 2 – Expansion (Months 3-4):
- Add geographic markets based on business priority
- Expand query coverage to 500-1000 total queries
- Integrate platform data into existing reporting dashboards
- Train content team on platform recommendations
- Establish governance for automated content publishing
Phase 3 – Optimization (Months 5-6):
- Enable full automation for low-risk content types
- Implement feedback loops between platform insights and content strategy
- Expand to additional business units or product lines
- Establish KPIs linking AI visibility to business outcomes
- Document ROI for budget renewal and expansion
Digital Agency Playbook
Agencies need multi-client rollout strategies and scalable processes that work across diverse industries.
Client Selection (Month 1):
- Start with 3-5 pilot clients representing different industries
- Choose clients with existing SEO retainers to minimize sales friction
- Select clients where AI visibility gaps are obvious and fixable
- Prioritize clients likely to renew and expand based on results
- Avoid starting with your most difficult or demanding clients
Agency Infrastructure (Months 1-2):
- Configure white-label branding and client-facing dashboards
- Establish standard packages and pricing tiers
- Create client onboarding templates and documentation
- Train account managers on platform capabilities and limitations
- Set up internal processes for quality review of automated content
Scale and Growth (Months 3-6):
- Document case studies from pilot clients
- Create sales collateral highlighting specific results and ROI
- Expand to additional clients based on pilot learnings
- Develop vertical-specific packages for high-opportunity industries
- Build recurring revenue models around AI visibility monitoring and optimization
Enterprise Multi-Brand Playbook
Large enterprises with multiple brands or business units need centralized governance with distributed execution.
Governance Framework (Month 1):
- Establish center of excellence for AI visibility standards
- Define brand safety rules and content approval workflows
- Create taxonomy for organizing brands, products, and markets
- Set data access controls and privacy policies
- Document escalation paths for edge cases and exceptions
Pilot Business Unit (Months 2-3):
- Select one business unit as pilot for full implementation
- Validate platform capabilities at scale (10,000+ queries)
- Test integration with existing martech stack
- Refine governance policies based on real-world issues
- Document learnings and best practices for rollout
Enterprise Rollout (Months 4-12):
- Phase rollout across business units based on priority and readiness
- Establish shared services for platform management and optimization
- Create cross-brand benchmarking and competitive intelligence
- Build executive dashboards showing portfolio-wide AI visibility
- Link AI visibility metrics to brand health and market share KPIs
Governance, Privacy, and Ethical Considerations
AI visibility monitoring raises questions about data privacy, competitive intelligence ethics, and responsible automation. Address these before full implementation.
Data Privacy and Compliance
Platforms querying AI systems collect data that may include personal information or proprietary content. Understand what data is collected, how it’s stored, and who has access.
Key questions for platform vendors:
- What data does the platform collect beyond brand mentions?
- Where is data stored and for how long?
- Who has access to query logs and results?
- How is data secured in transit and at rest?
- What are data retention and deletion policies?
- How does the platform handle GDPR, CCPA, and other privacy regulations?
Establish internal policies for handling sensitive queries or mentions. Not every visibility gap should be shared across your organization or with platform vendors.
Competitive Intelligence Ethics
Monitoring competitor mentions in AI systems raises ethical questions. Where’s the line between competitive intelligence and surveillance?
Ethical guidelines to consider:
- Monitor public information only – don’t attempt to access proprietary data
- Focus on understanding market positioning, not copying competitor strategies
- Use insights to improve your own content and messaging, not to disparage competitors
- Respect intellectual property and don’t scrape copyrighted content
- Be transparent with stakeholders about monitoring scope and methods
Document your ethical standards and train teams on acceptable use. One misstep can damage reputation and create legal exposure.
Responsible Automation
Automated content creation and publishing introduces risks around quality, accuracy, and brand safety. Not every visibility gap should trigger automated content.
Implement guardrails for automation:
- Content review thresholds – Require human review for high-risk topics or large changes
- Factual accuracy checks – Validate claims and statistics before publishing
- Brand voice consistency – Ensure automated content matches brand guidelines
- Legal and compliance review – Flag content requiring legal approval
- Rollback procedures – Quick methods to unpublish problematic content
Start with human-in-the-loop workflows where automation suggests but humans approve. Expand full automation only after validating quality and safety controls.
Frequently Asked Questions
How long does it take to see results from AI visibility optimization?
Initial improvements often appear within 2-4 weeks after publishing optimized content. AI systems like ChatGPT and Claude can reflect new content within days. Google AI Overviews typically take longer, following traditional indexing patterns of 1-3 weeks. Sustained visibility gains require ongoing optimization over 3-6 months as you address more gaps and refine content quality.
What’s the difference between monitoring tools and optimization platforms?
Monitoring tools track brand mentions and generate reports. They tell you what’s happening but don’t close visibility gaps. Optimization platforms go further by analyzing gaps, creating content to address them, and measuring results. Platforms like Refinea automate the full loop from detection to publishing. Choose monitoring tools if you have strong content teams who can act on insights. Choose optimization platforms if you need speed and scale.
Can small businesses afford enterprise AI visibility platforms?
Pricing varies widely. Enterprise platforms often start at $2,000-5,000 per month for basic packages. Small businesses might start with manual monitoring using free tools, then upgrade as budgets allow. Some platforms offer agency partnerships where you access the technology through a marketing agency’s white-label program. This provides enterprise capabilities at small business budgets through shared infrastructure.
How do I choose between building custom tools and buying a platform?
Build custom tools when you have unique requirements no platform addresses and engineering resources to maintain them long-term. Buy platforms when speed to market matters and you need capabilities that would take months to build. Most teams underestimate the ongoing cost of maintaining custom tools as AI systems evolve. Calculate total cost of ownership over 3 years, not just initial development cost.
What happens if AI systems change their APIs or shut off access?
This is a real risk. Platforms with diverse data sources reduce dependency on any single API. Look for platforms that use multiple collection methods – APIs, browser automation, and hybrid approaches. Ask vendors about their contingency plans if major AI systems restrict access. Platforms with 150+ parallel workers and multiple collection methods adapt faster than those dependent on single API endpoints.
How accurate is automated mention detection compared to manual checking?
Good platforms achieve 90-95% accuracy measured by F1 Score. This means they correctly identify most mentions and rarely flag false positives. Accuracy varies by language, with English typically most accurate and less common languages showing lower precision. Always validate platform data against manual checks during evaluation. Require accuracy above 90% before trusting the platform for optimization decisions.
Should agencies white-label platforms or build their own solutions?
White-label programs let agencies offer AI visibility services without building technology. This makes sense for agencies focused on client services rather than product development. Revenue share models (60-70% is typical) provide recurring income without engineering overhead. Build your own solution only if you have significant technical resources and see platform development as a core differentiator. Most agencies are better served partnering with established platforms.
What metrics should I track to prove ROI from AI visibility investments?
Start with mention rate and citation quality improvements. Track these against baseline measurements from before platform implementation. Connect visibility gains to business outcomes – website traffic from AI referrals, lead generation, brand search volume increases. Calculate time savings from automation versus manual monitoring and content creation. Show ROI in both efficiency gains and revenue impact. Expect 6-12 months to demonstrate clear ROI from visibility improvements.
Making Your Decision
You now have a framework for evaluating AI visibility platforms objectively. Apply these six criteria consistently across any solution you consider.
- Measure mention rate, citation quality, and share of voice with standardized formulas
- Verify data accuracy above 90% before trusting platform insights
- Test geographic precision and language coverage for your markets
- Validate automation speed and reliability through controlled experiments
- Compare alternative solution patterns – platform, point tools, or custom build
Run a 30-day evaluation protocol before committing to annual contracts or large implementations. Set minimum acceptable thresholds for each metric and proceed only when platforms meet or exceed them.
AI-driven brand visibility will only grow more important as AI Overviews and chat engines handle more queries. The brands that establish measurement frameworks and optimization processes now will have compounding advantages over those waiting for the market to mature.
Start with a baseline assessment of your current AI visibility. Get your AI Visibility Score to understand where you stand before evaluating platforms or making investment decisions.
For teams ready to explore unified solutions, review SERP Intelligence for AI Overviews tracking and Chat Intelligence for recommendations in ChatGPT, Claude, Gemini, Perplexity, Grok to understand how comprehensive platforms approach the measurement challenge.
When visibility gaps become clear, investigate how automated remediation works. The Content & Action Engine to close visibility gaps automatically demonstrates the next evolution beyond monitoring-only tools. You can also explore the platform overview for the complete loop.
Evaluate platforms against your specific requirements, not vendor marketing claims. Use the framework, run controlled tests, and make decisions based on empirical results. Your brand’s visibility in AI systems depends on it.