
Leaders constantly ask marketing agencies for proof of brand presence inside AI-generated answers. Most teams lack cross-model tracking or a way to turn findings into action. The best AI visibility tool tracks brand mentions across Google AI Overviews and major chat assistants.
Top platforms pair monitoring with automated execution and executive metrics. This guide explains how AI systems cite sources and the exact metrics that matter. You will learn a practical workflow from detection to measurable lift.
We wrote this for advanced marketers applying GEO (Generative Engine Optimization) standards. You need distinct approaches to monitor different types of AI answers.
- Extract citations and measure your brand mention rate over time.
- Generate targeted content to fill identified gaps.
- Update your executive rollup with new visibility scores.
Why AI Brand Visibility In Answers Matters
AI assistants increasingly mediate online discovery and product recommendations. Users ask questions and expect immediate answers rather than a list of links. Your brand presence depends on mentions and recommendation frequency.
Traditional blue links no longer guarantee visibility in these new interfaces. Geography and language variants change which sources bots cite. A brand might appear in a New York search but vanish in London.
Tracking this variance requires specialized software to monitor AI brand mentions accurately. Effective AI Overviews monitoring and chatbot recommendation tracking solve this problem.
- Clients expect proof of placement in ChatGPT and Google.
- Competitors might capture the AI share of voice in your niche.
- Local markets require specific tracking configurations.
How AI Systems Generate Answers And Cite Sources
Models do not simply repeat memorized text. They use complex systems to find and display information. You must understand these mechanics to rank well.
Retrieval And Grounding
Bots use web search and index lookups to find current data. Many platforms employ retrieval augmented generation (RAG) pipelines. These pipelines connect the language model to external knowledge bases.
This process helps ground the answers in factual reality. It prevents the bot from guessing and reduces errors.
Source Selection
Algorithms score sources based on relevance and recency. They use authority heuristics to pick the most trustworthy domains. High-authority sites often win these citations.
- The bot analyzes the user prompt for intent.
- The system retrieves relevant documents from its index.
- The model synthesizes the information into a readable answer.
Citation Rendering
Models display citations in several different ways. Some use inline links directly in the text. Others prefer footnote-style references at the end of the response.
Many platforms use implicit source attribution in AI answers without direct links. You must track all these variations to understand your true presence.
Variance By Model
Different assistants handle evidence and links differently. GPT, Claude, Gemini, Grok, and Perplexity all use unique citation rules. A source cited by Claude might be ignored by Gemini.
Marketers must understand verification approaches across these tools. Reviewing hallucination mitigation strategies helps teams build reliable reporting.
Recent AI hallucination statistics show why verification remains a priority. You cannot trust unverified bot outputs.
Methods And Tools To Track AI Visibility
Single-channel dashboards miss too much data. Agencies use SERP Intelligence to capture AI Overviews with exact language parameters. This captures the Google environment perfectly.
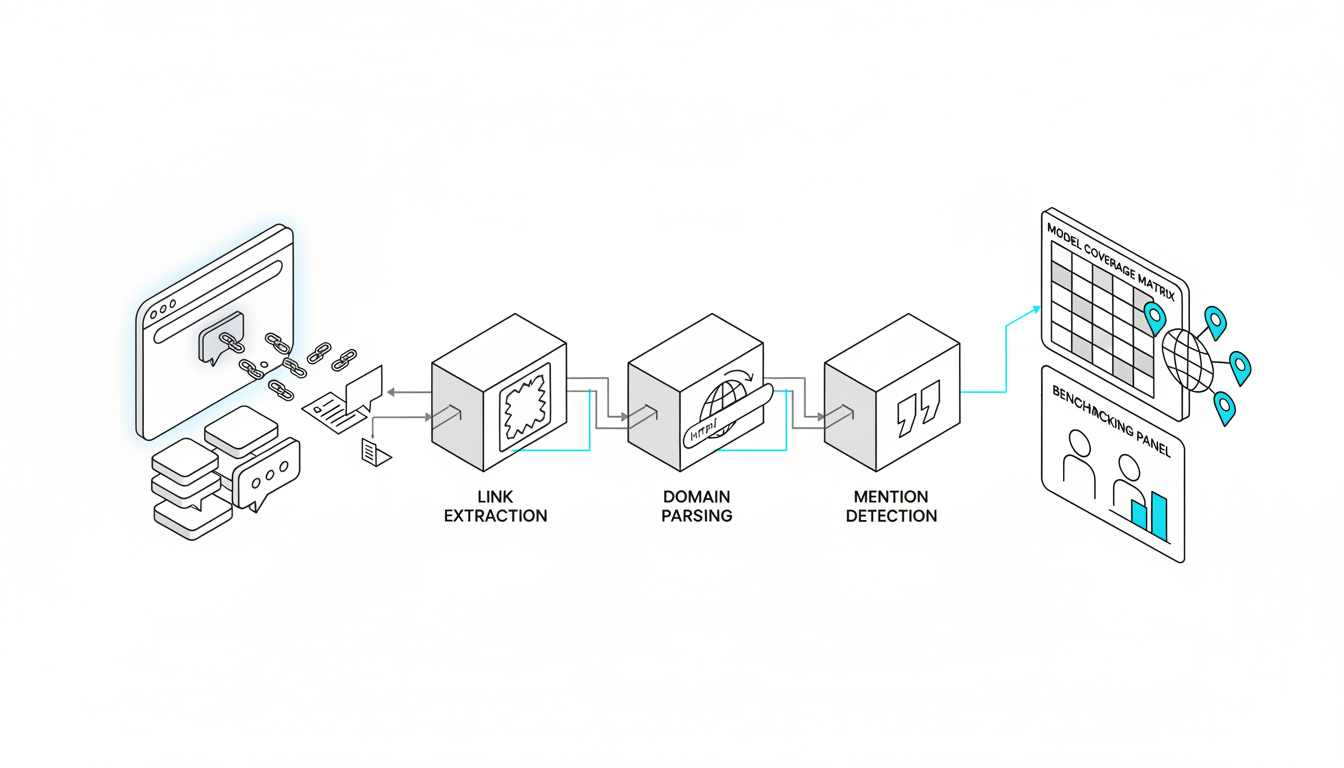
Teams deploy Chat Intelligence to run scripted prompts across major bots. This covers GPT, Claude, Gemini, Grok, and Perplexity. A complete tracking methodology includes multiple steps.
- Extract visible links from the generated text.
- Parse source domains to find brand overlaps.
- Identify exact mention phrases within the response.
- Build a model coverage matrix to track included locales.
This enables accurate model coverage benchmarking against competitors. Running the same prompt across multiple models surfaces disagreements. Suprmind runs these comparisons to highlight where models diverge.
You can also use AI website analytics to see which bots crawl your site. This reveals what content AI systems consume.
Metrics That Matter
Raw data means nothing without clear measurement standards. Executives need numbers they can track week over week. Track these core metrics to prove your value.
- Mention rate: The percentage of runs where the bot names your brand.
- Citation frequency: The total count of links per model and locale.
- AI share of voice: Your brand mentions compared to competitors.
Watch your visibility trends over time to see directional changes. Assign an Impact Score to rank gap opportunities by potential effect.
Agencies package these numbers into executive reporting indices. An AI Visibility Score provides a fast audit of your total presence. You can also track your AI Authority Rank against industry peers.
Evaluation Criteria: What Makes A Tool Best
Not all tracking platforms offer the same depth. You need a system that pairs analytics with an execution loop. Look for specific capabilities when evaluating an AI brand mention analytics platform.
- Dual coverage of both AI Overviews and chat assistants.
- City-level visibility tracking and language variants for global campaigns.
- Stable prompts with time-stamped captures for reliable runs.
- RAG-assisted grounding and source reconciliation for verification.
- Executive-friendly indices and APIs for automated rollups.
Top platforms include an action engine to close gaps. This lets you generate and publish content directly from the insights. Agencies often seek a white-label partnership to resell these capabilities.
Practical Workflow Template
Data collection is just the first step. You must turn those insights into published content that changes bot behavior. Follow this exact sequence to improve your citation frequency analysis.
- Select 200 to 1,000 priority queries by market and language.
- Schedule cross-model prompt runs and capture AI Overviews by city.
- Extract mentions to compute your mention rate and share of voice.
- Identify gaps against competitors and assign Impact Scores.
- Generate targeted FAQs and local pages to fill those gaps.
- Measure your trend lift weekly and iterate your prompts.
- Update your executive rollup with new visibility scores.
This loop moves you from passive monitoring to active improvement. See how a content action engine automates this entire process. Using GEO tools makes this workflow highly repeatable.
Risk Management: Hallucinations And Reliability
AI models sometimes invent facts or hallucinate citations. You must verify the data before showing it to clients. Use cross-model consensus to flag uncertain answers.
If only one model makes a claim, treat it with suspicion. Apply RAG and citation reconciliation to verify claims. Proper RAG implementation can reduce hallucinations by up to 71 percent.
- Log model versions for accuracy.
- Save prompts to reproduce results.
- Record timestamps to create an audit trail.
Disagreement analysis helps you spot factual inconsistencies quickly. This protects your agency from reporting false data.
Key Takeaways
Mastering AI search requires the right combination of tools and tactics. Keep these core principles in mind as you build your strategy.
- Top platforms require dual coverage and an execution loop.
- Measure your mention rate and share of voice before taking action.
- Use disagreement analysis to verify data and build trust.
- Executive indices accelerate alignment and secure budget approvals.
- City-level tracking exposes hidden competitive differences.
Frequently Asked Questions
How do I compare AI visibility platforms fairly?
Use the exact same prompts, locales, and time windows. Track the mention rate and citations across models to audit their execution capabilities.
Do AI assistants always show citations?
No. Some models summarize information without explicit links. You need parsing rules for visible citations and screenshot evidence to prove placement.
Why track city-level or language variants?
Answers vary heavily by geography and language. Localized tracking exposes hidden opportunities that national searches miss.
How do I reduce hallucination risk in monitoring?
Run cross-model comparisons and apply source reconciliation. Log all versions to maintain a reliable audit trail.
Which metrics should I show executives?
Present your AI Visibility Score and share of voice. Show clear trends after you publish new optimized content.